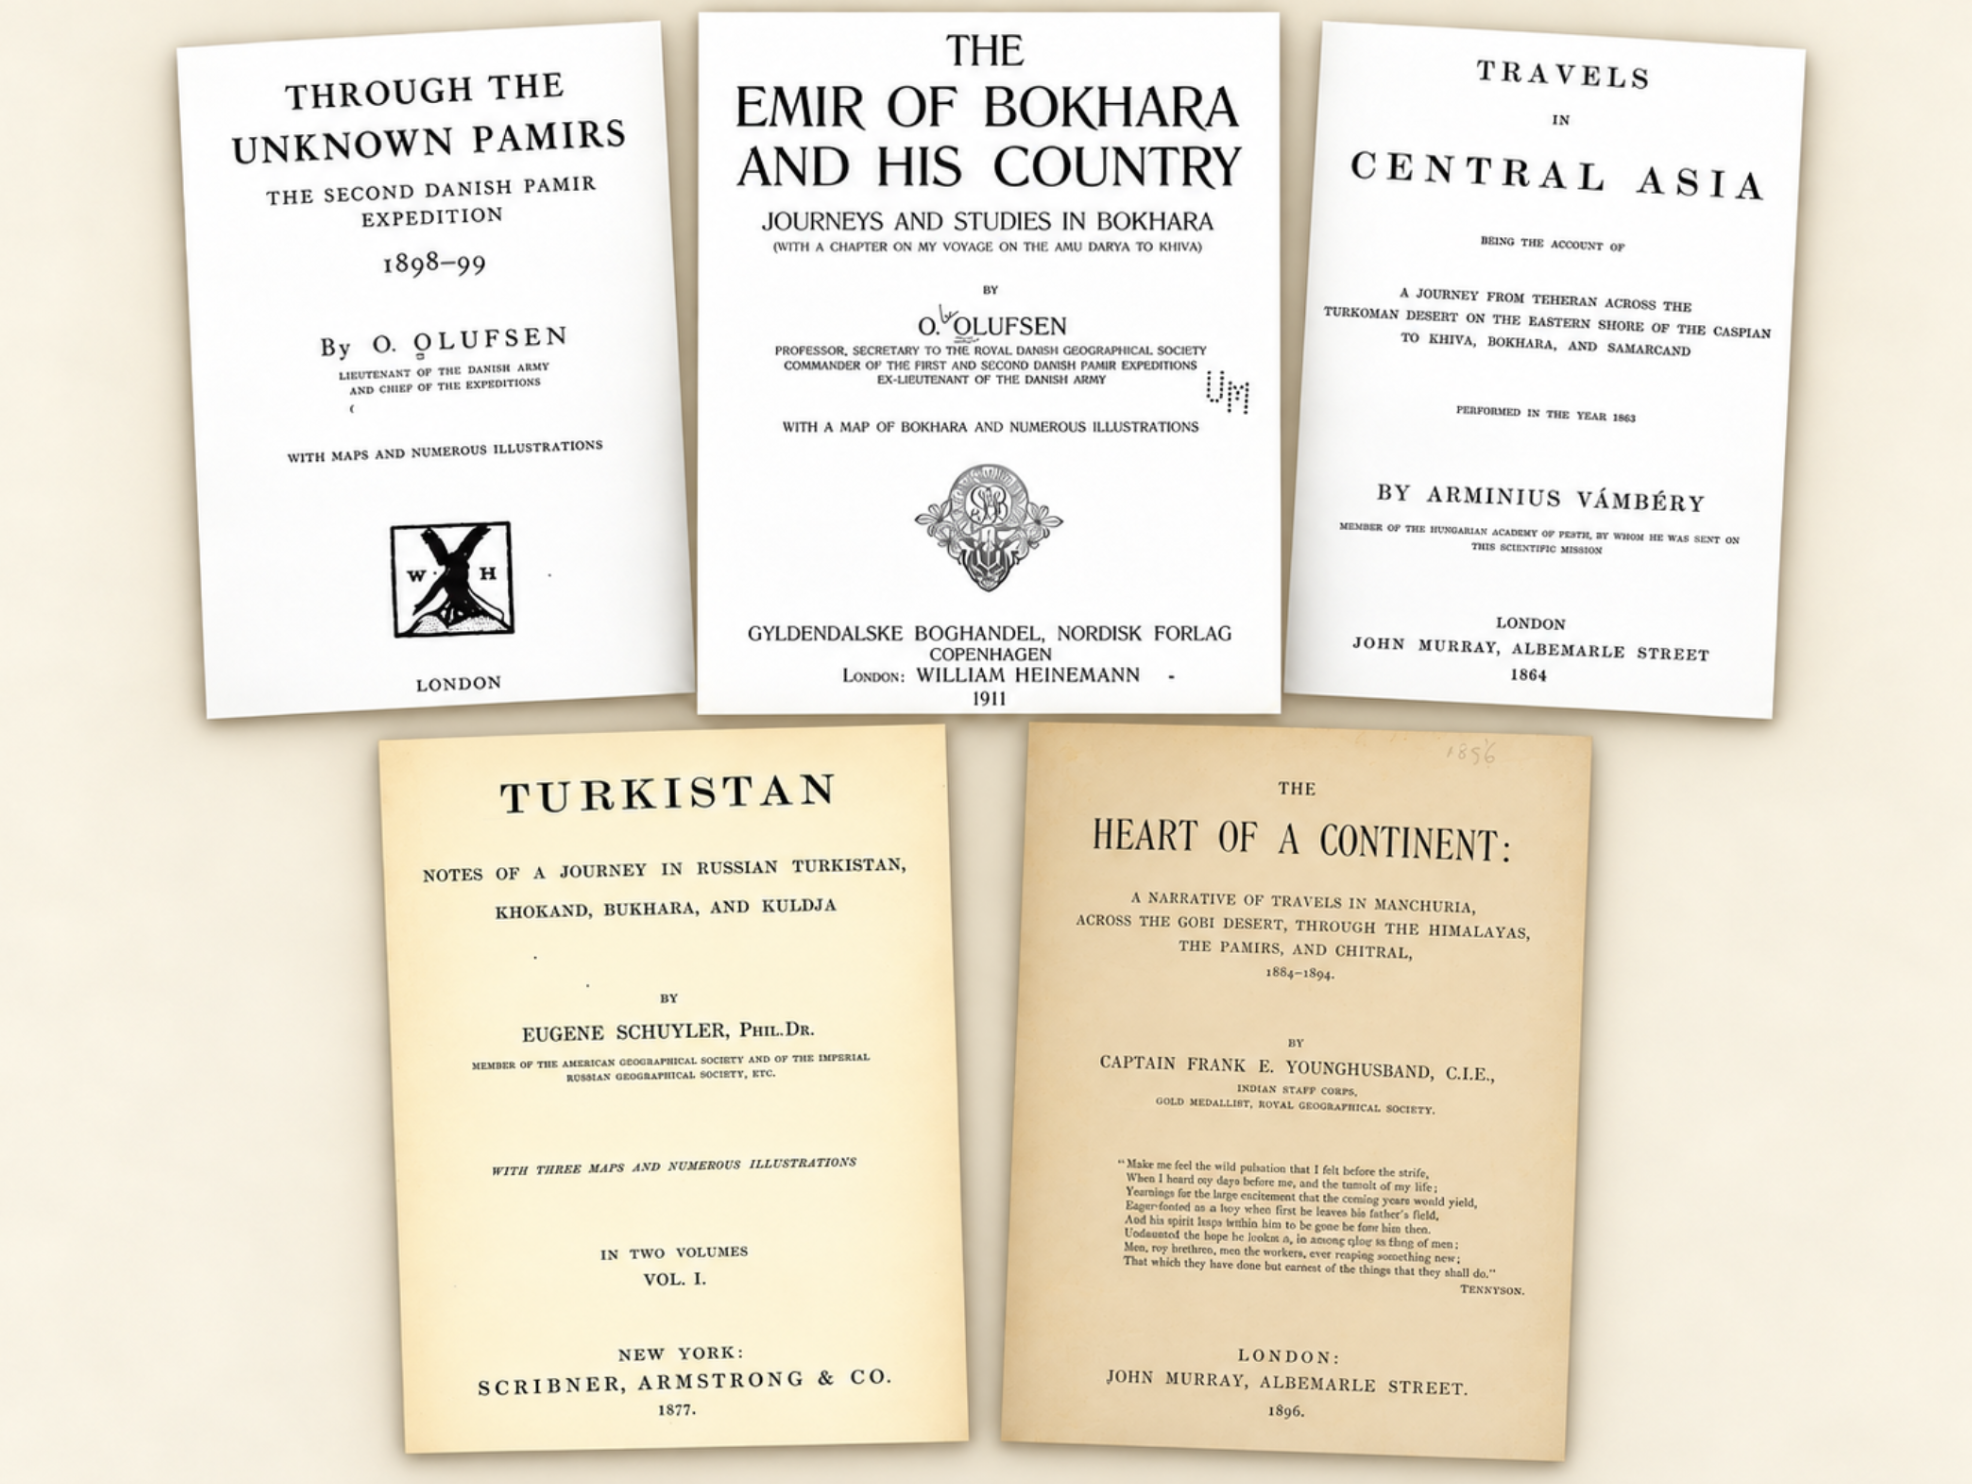
From Scanned Travel Books to a Page-Aware Corpus: Testing Microsoft Foundry for Historical Research on Central Asia
This is a guest piece by Aizat Ishembieva. This post describes how structured text extraction and the creation of a…
This is a guest piece by Aizat Ishembieva. This post describes how structured text extraction and the creation of a…
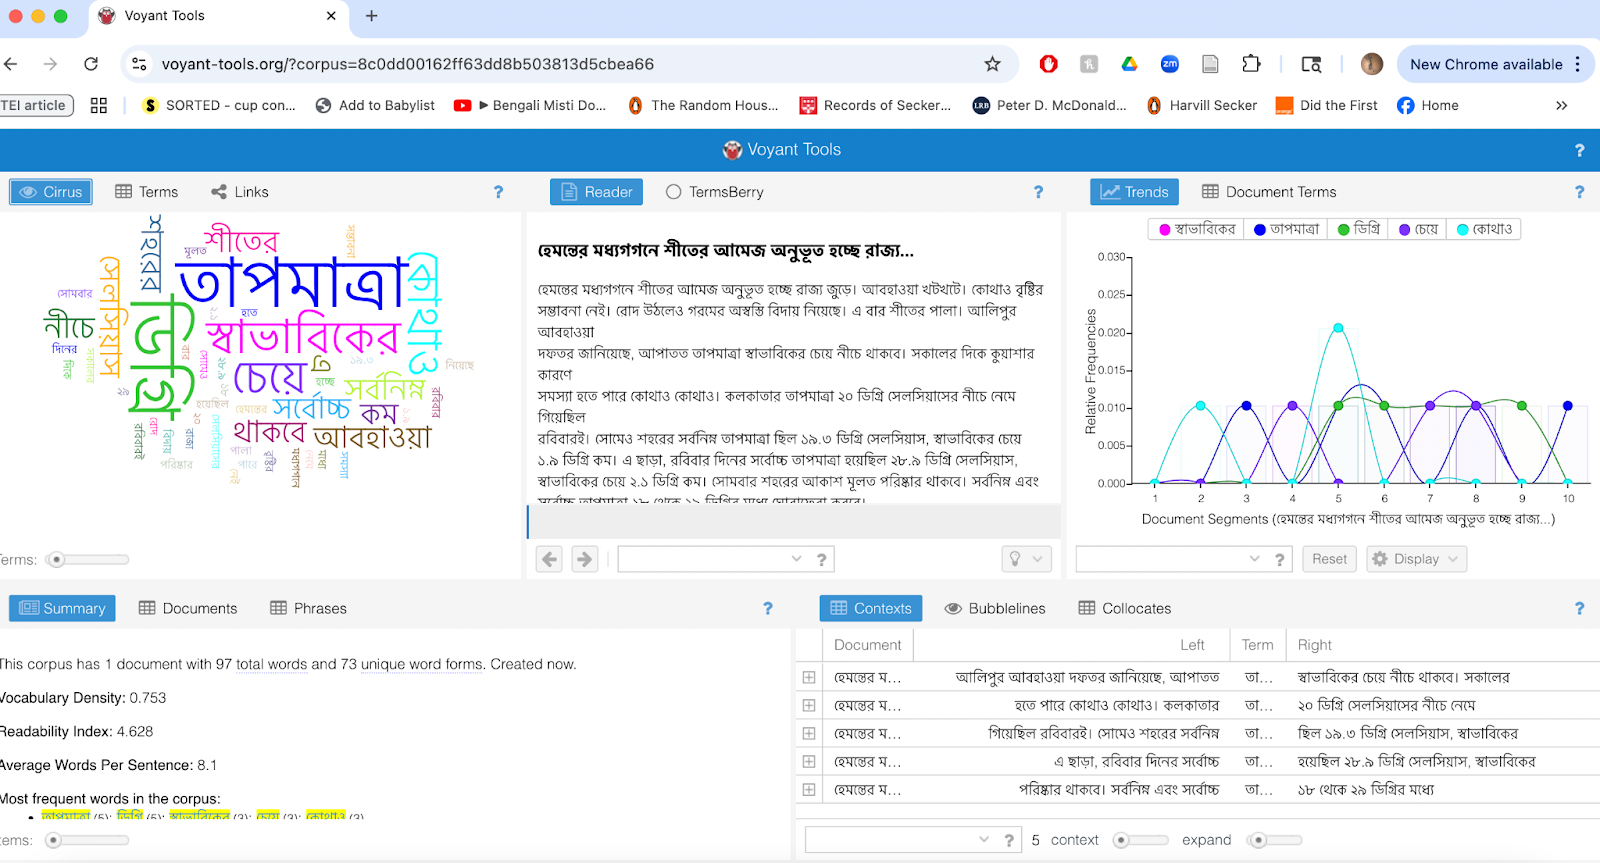
In designing an introductory Digital Humanities class, I am often faced with the question of how best to incorporate linguistic…
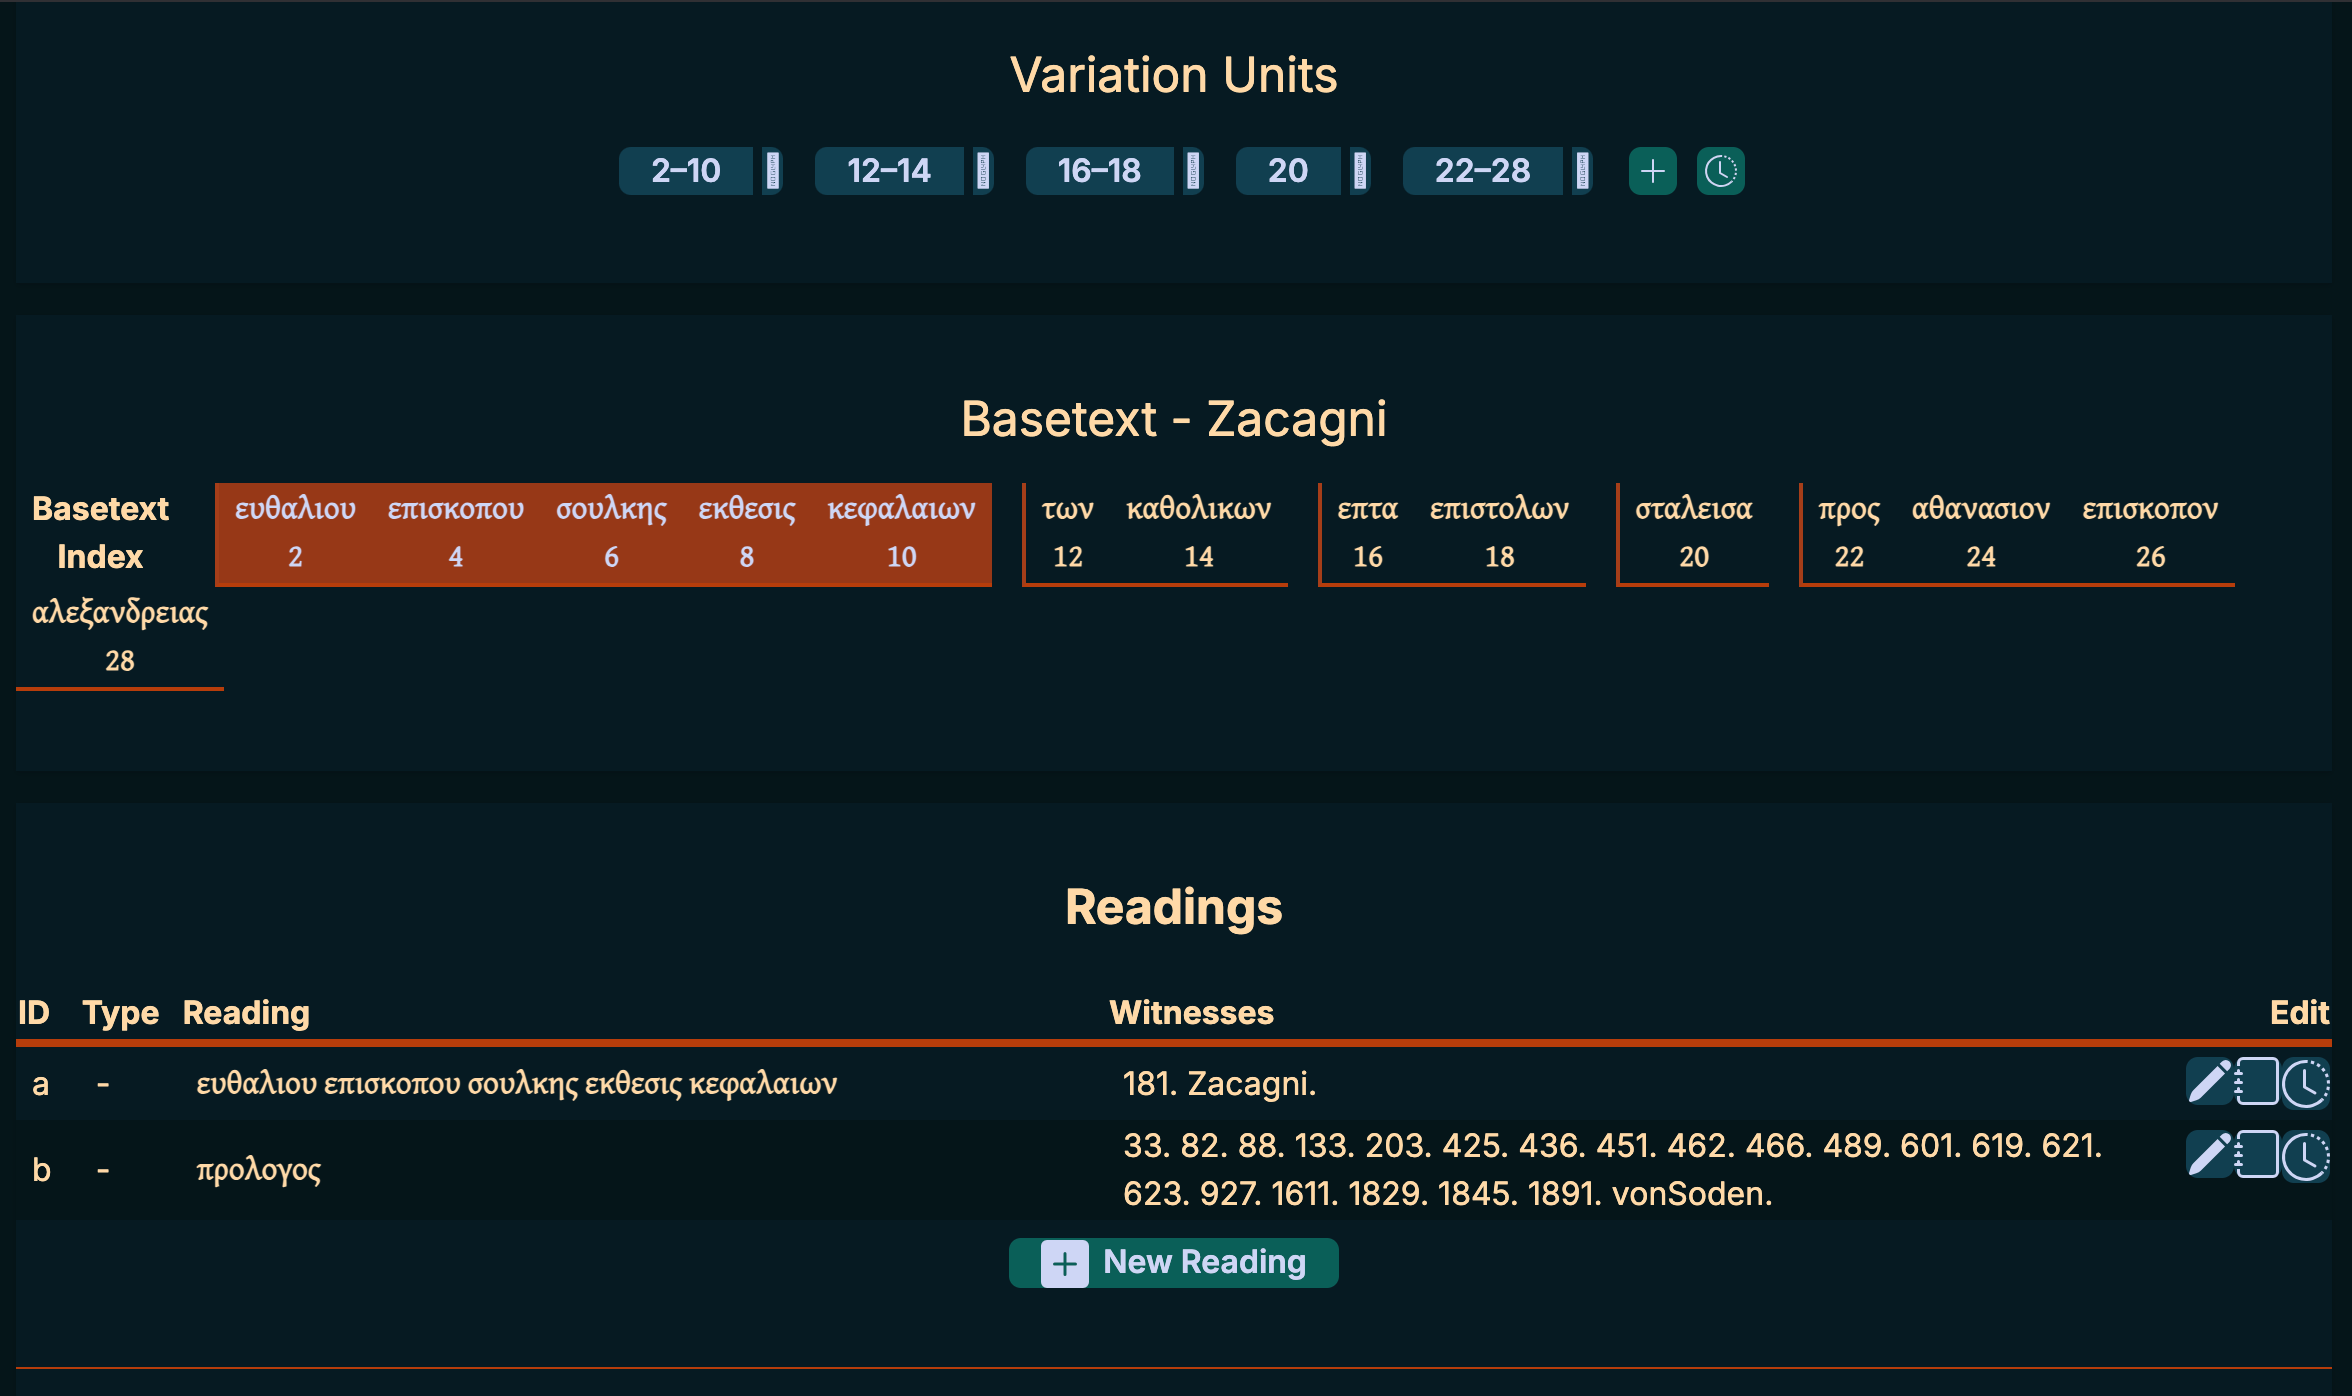
In my last post, I explored how to collate TEI XML transcriptions of Greek New Testament manuscripts, yielding a TEI…
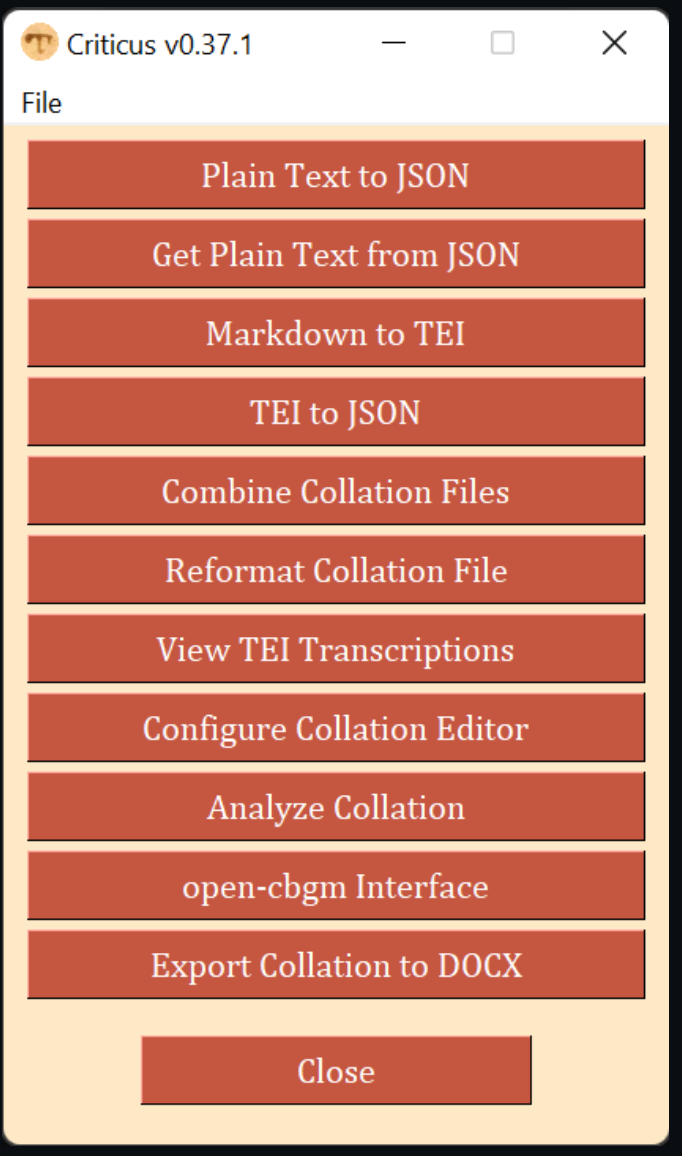
Introduction In my last post, I explored tools in a software package called Criticus that helps move from transcription to…
Introduction In my last few posts, I explored how Python could be used to do some codicological analysis of manuscripts…
In an earlier post here on The Digital Orientalist, Mariana Zorkina introduced the topic of regular expressions (or in short…
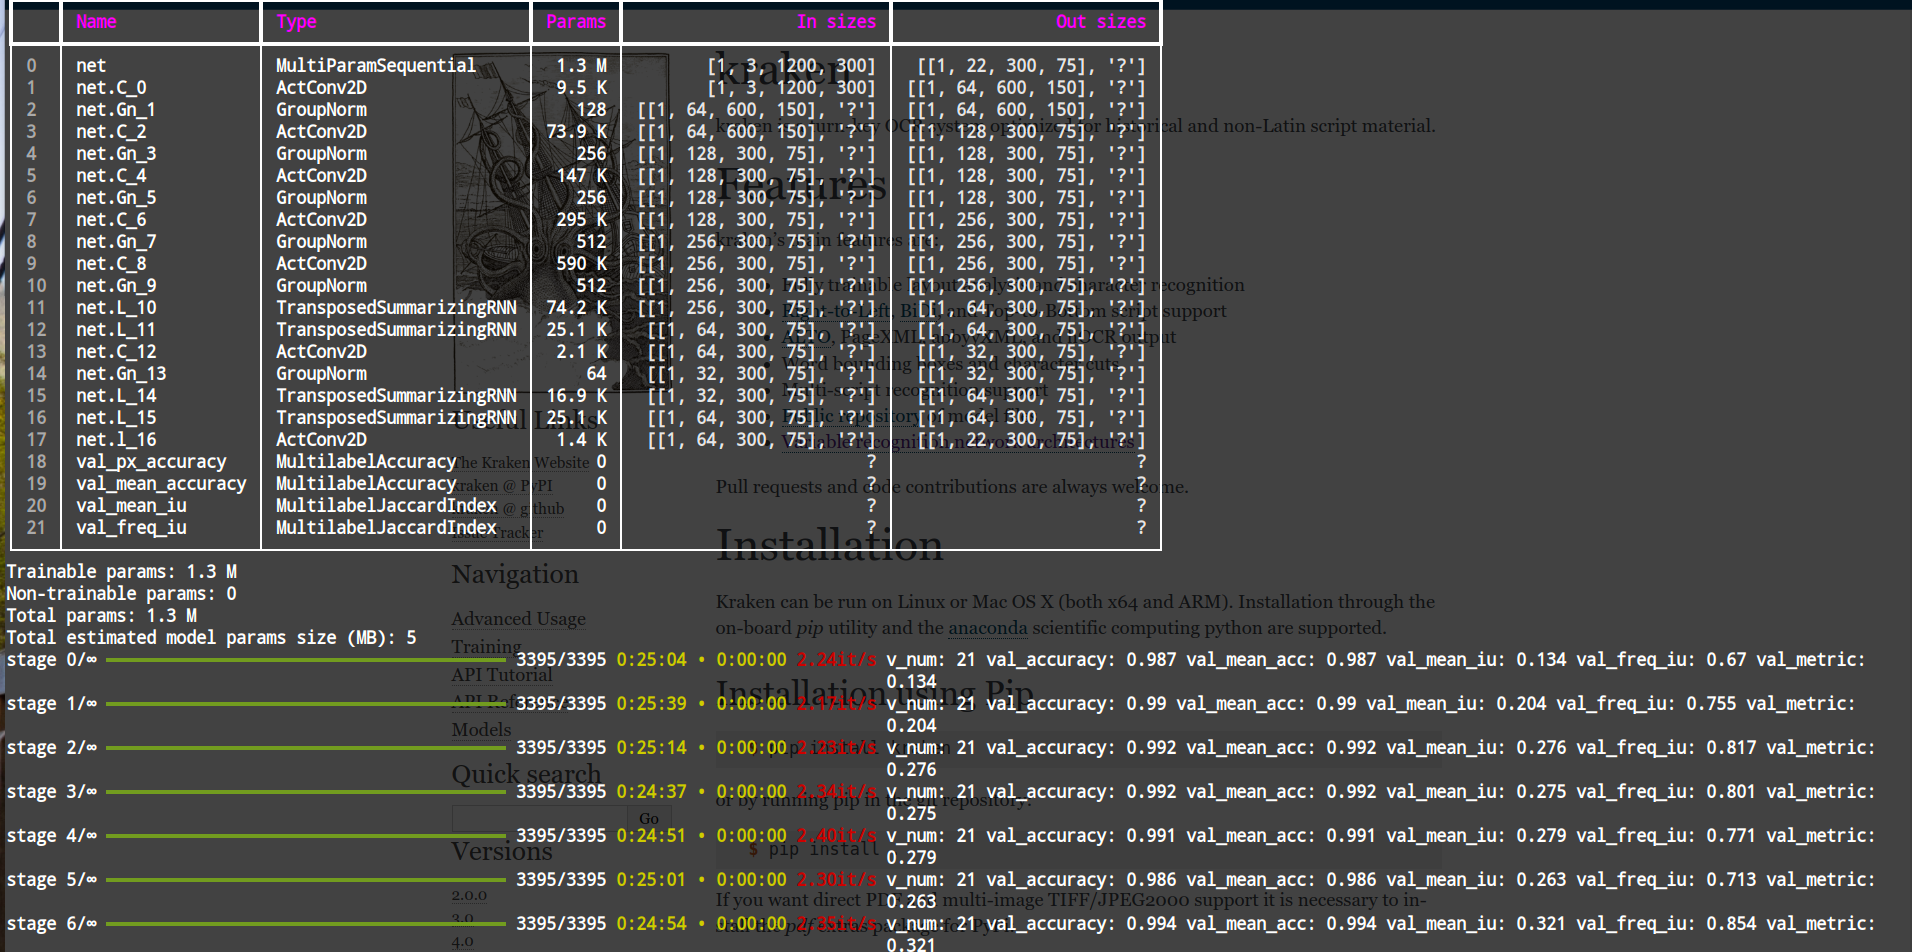
Learn about Kraken’s segmentation model and the process of training our own custom segmentation models for layout analysis tasks.
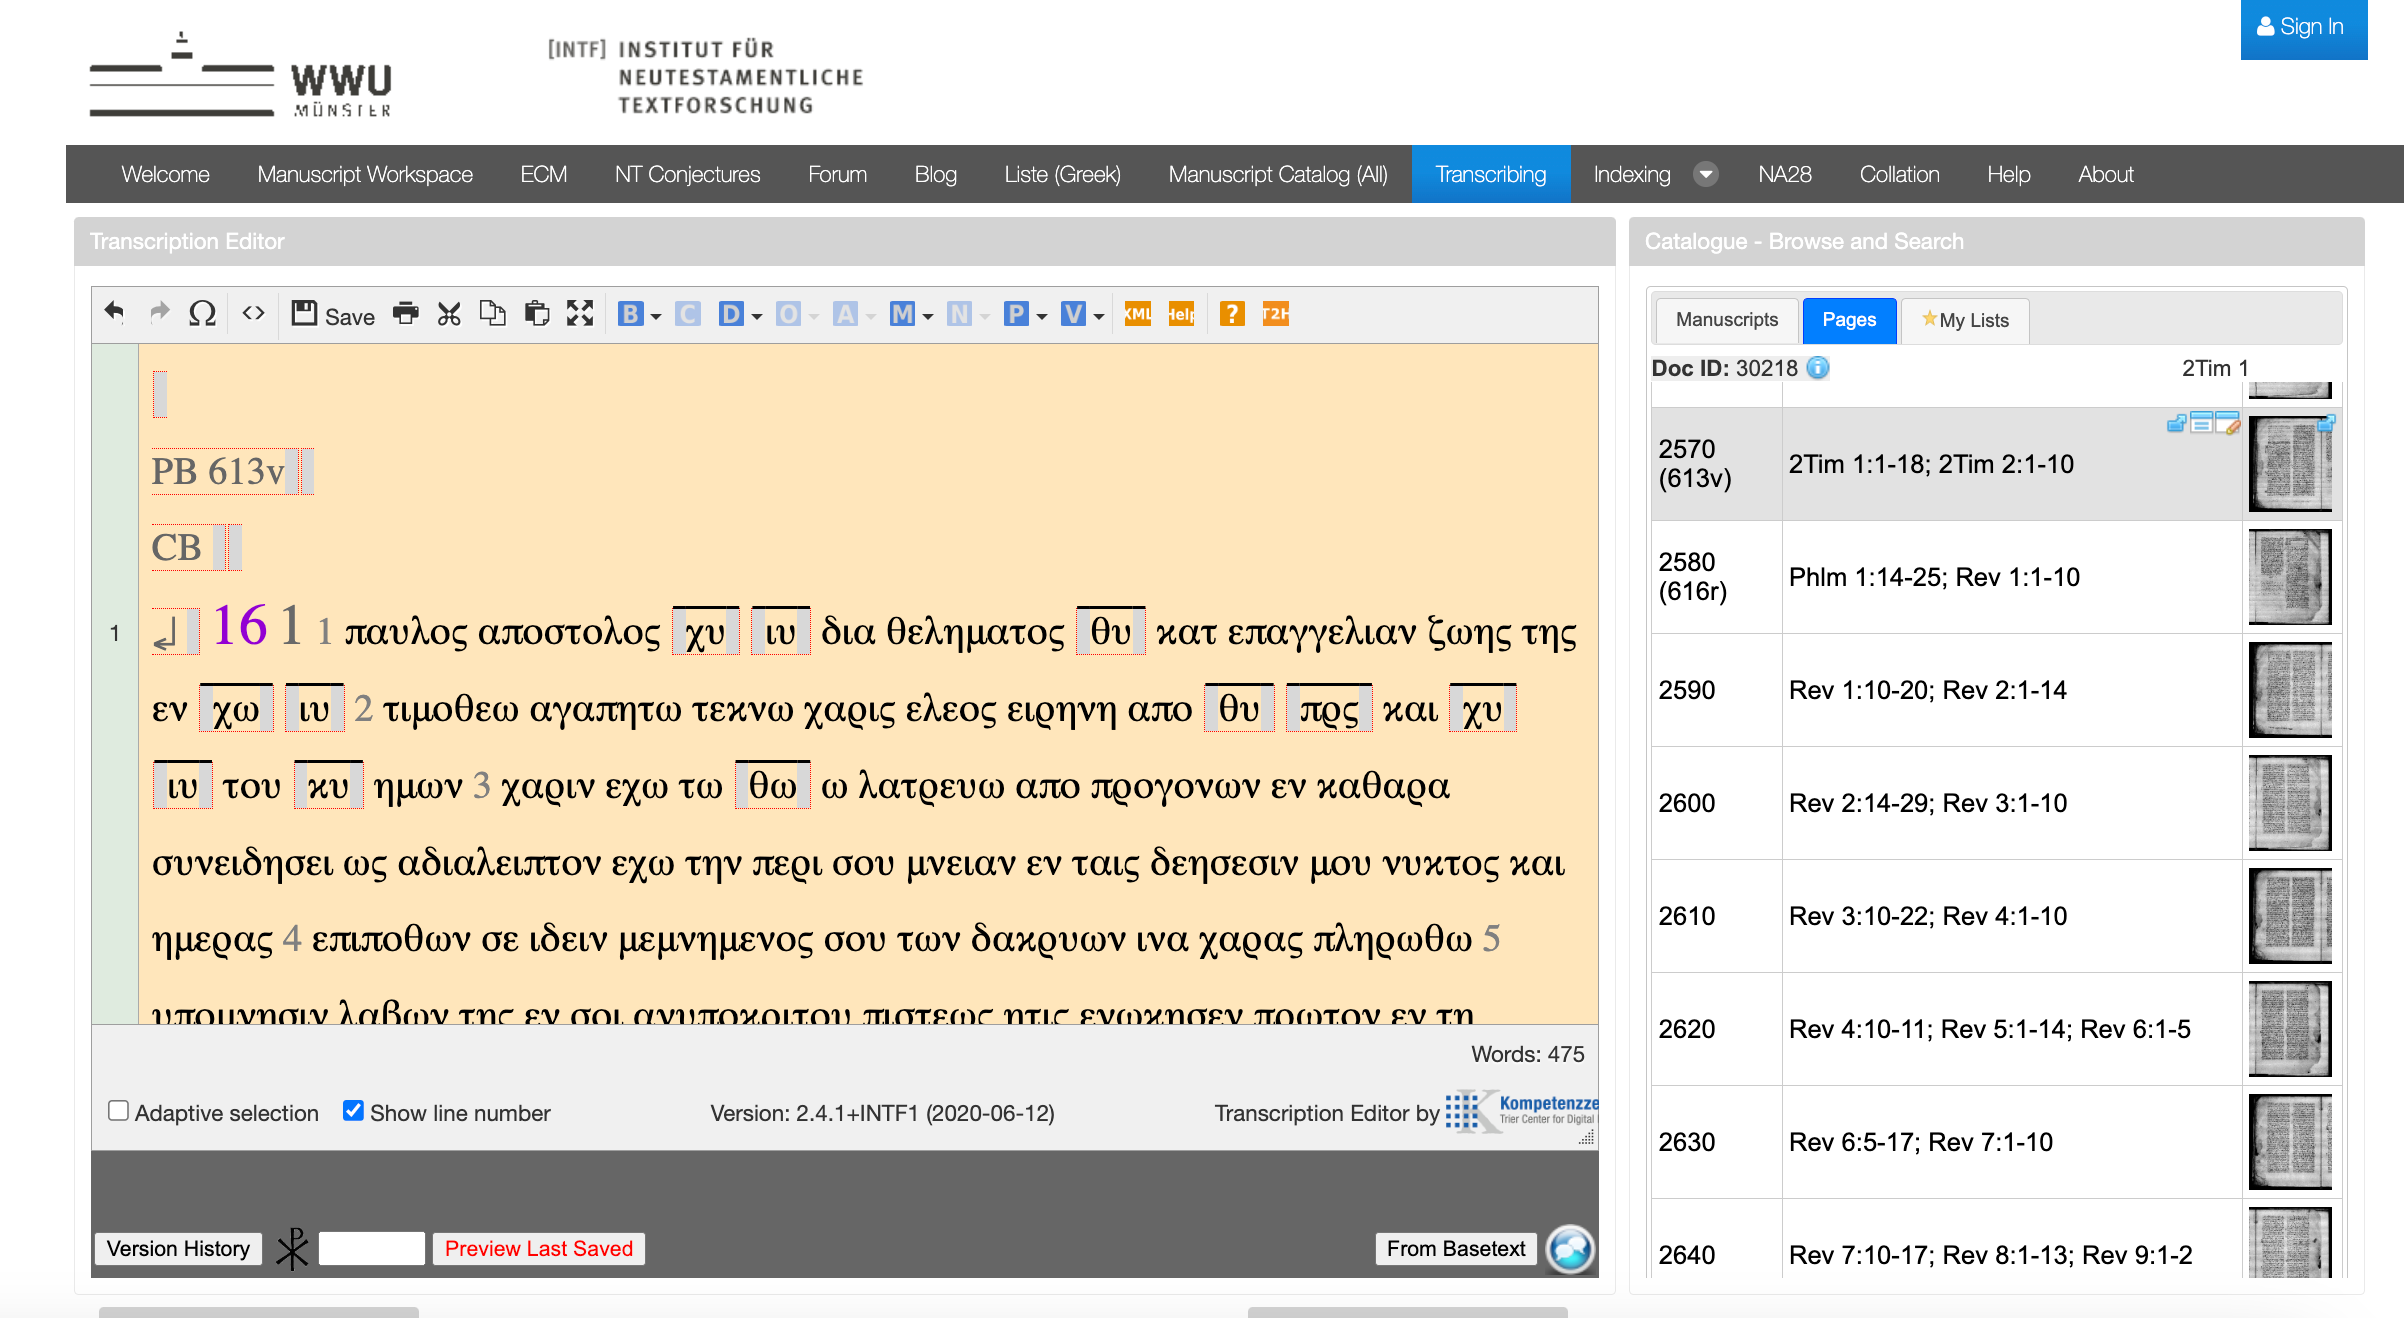
This post continues my series on using the New Testament Virtual Manuscript Room (NTVMR) for researching and transcribing Manuscripts of…
Greg Paulson has already written a very helpful introduction to the New Testament Virtual Manuscript Room (NTVMR) as a guest…