I have tried all the writing programs, so you don’t have to
I have tried all the writing programs (well, almost), so you don’t have to. In the course of the last…
I have tried all the writing programs (well, almost), so you don’t have to. In the course of the last…
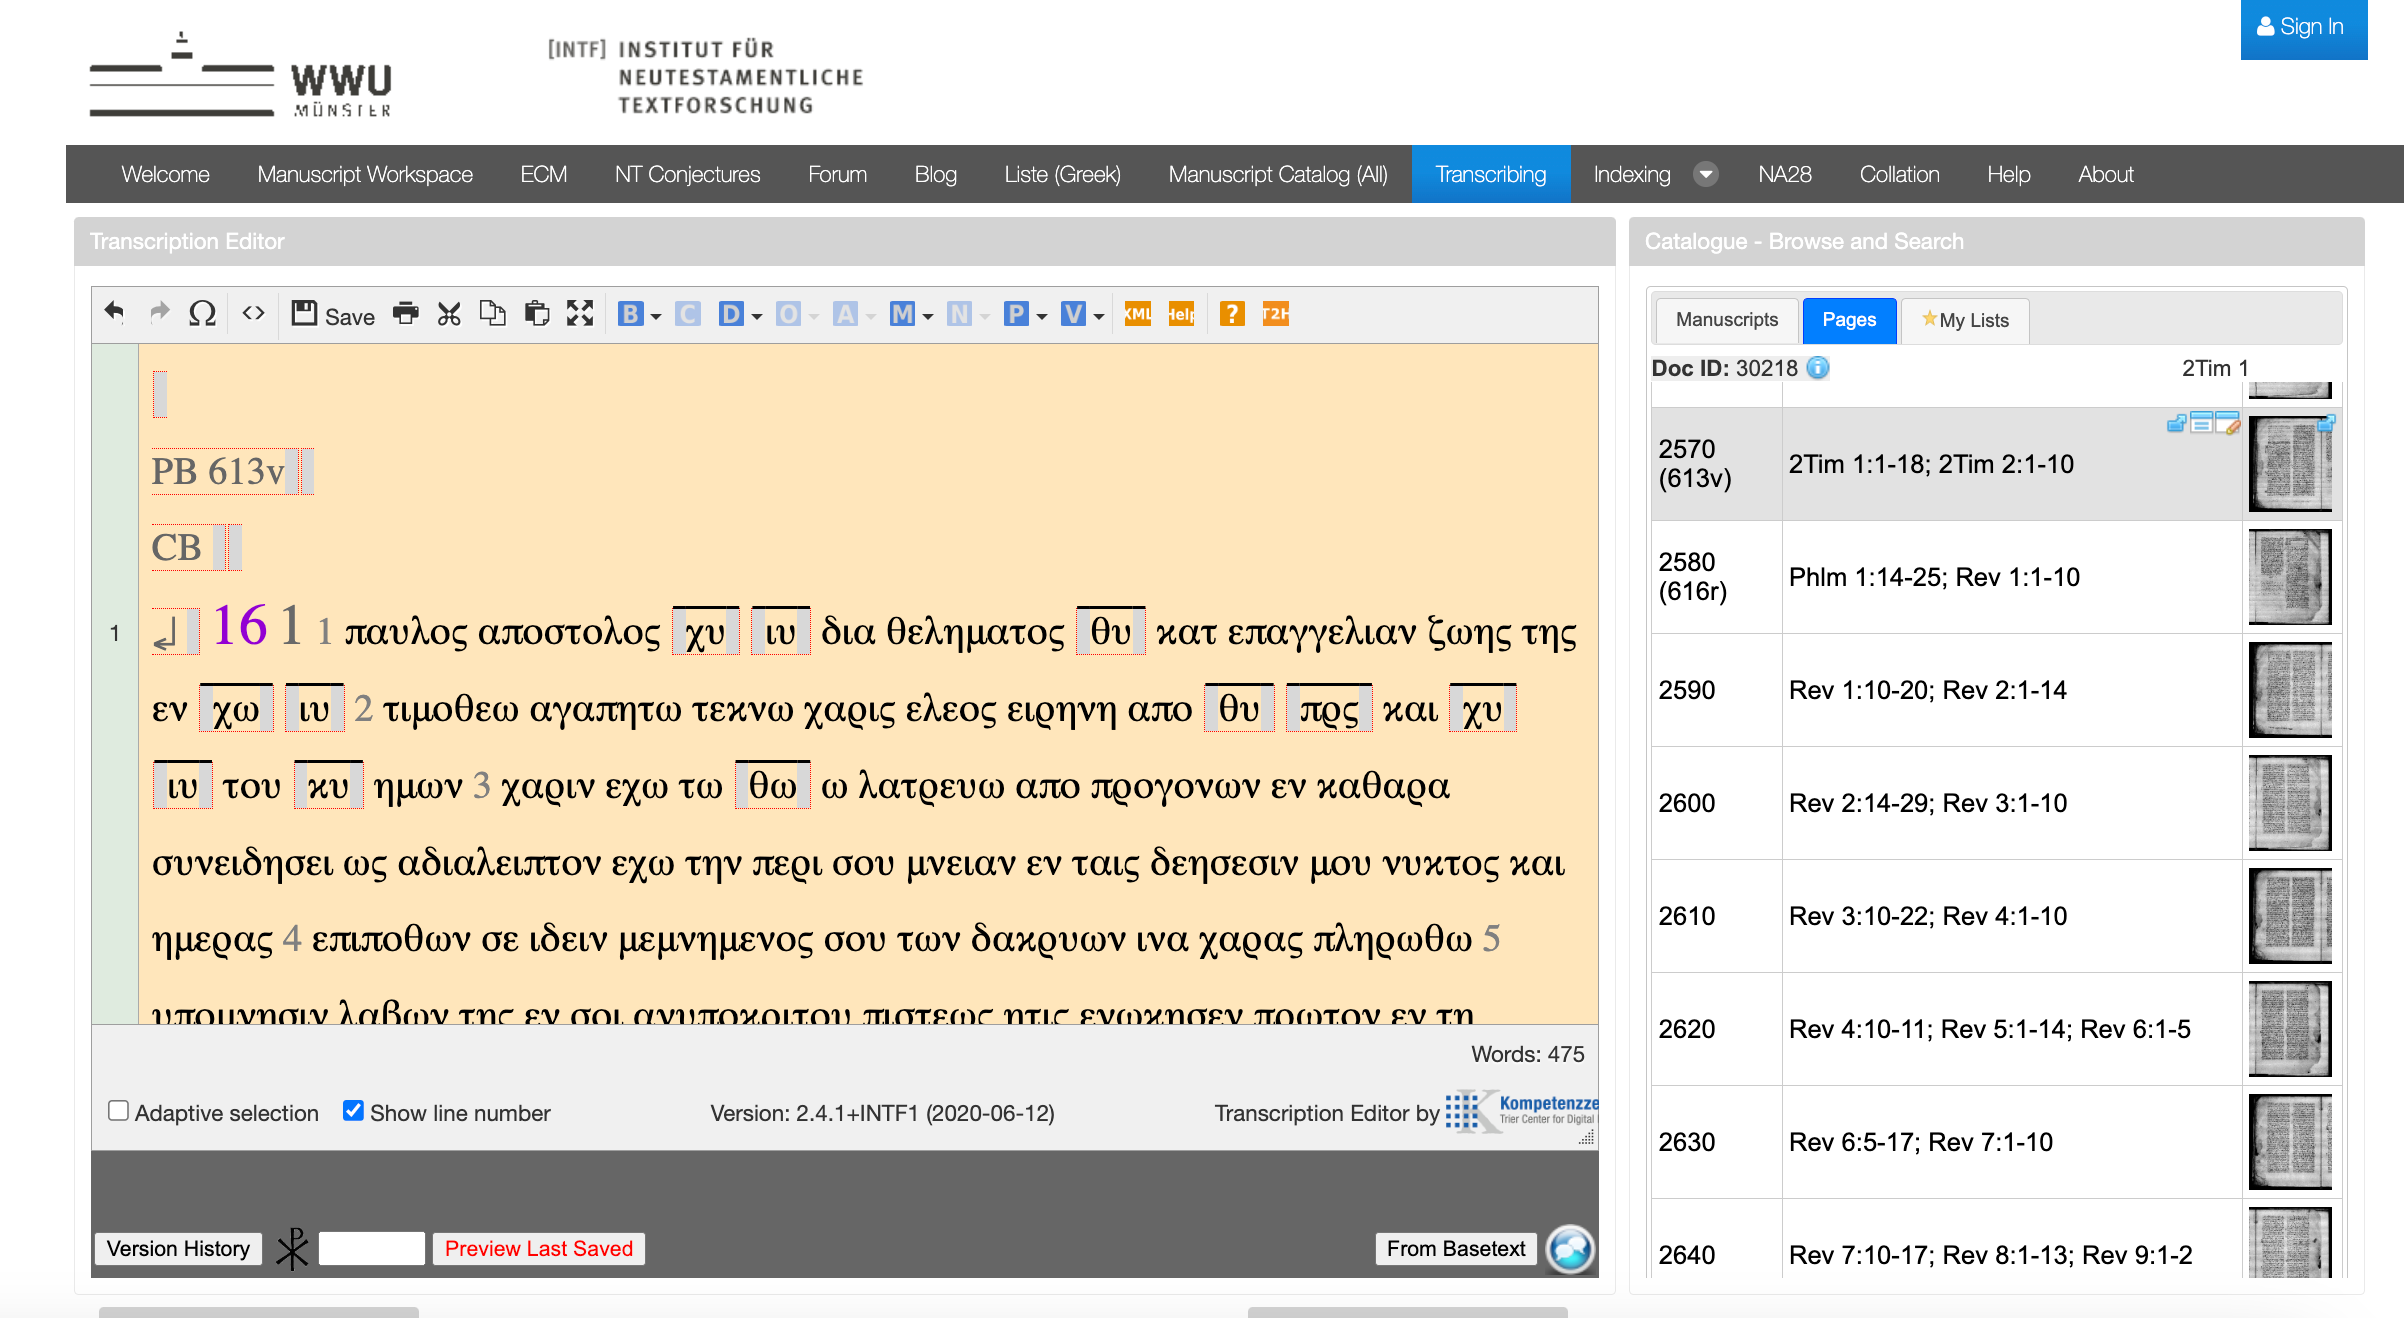
This post continues my series on using the New Testament Virtual Manuscript Room (NTVMR) for researching and transcribing Manuscripts of…
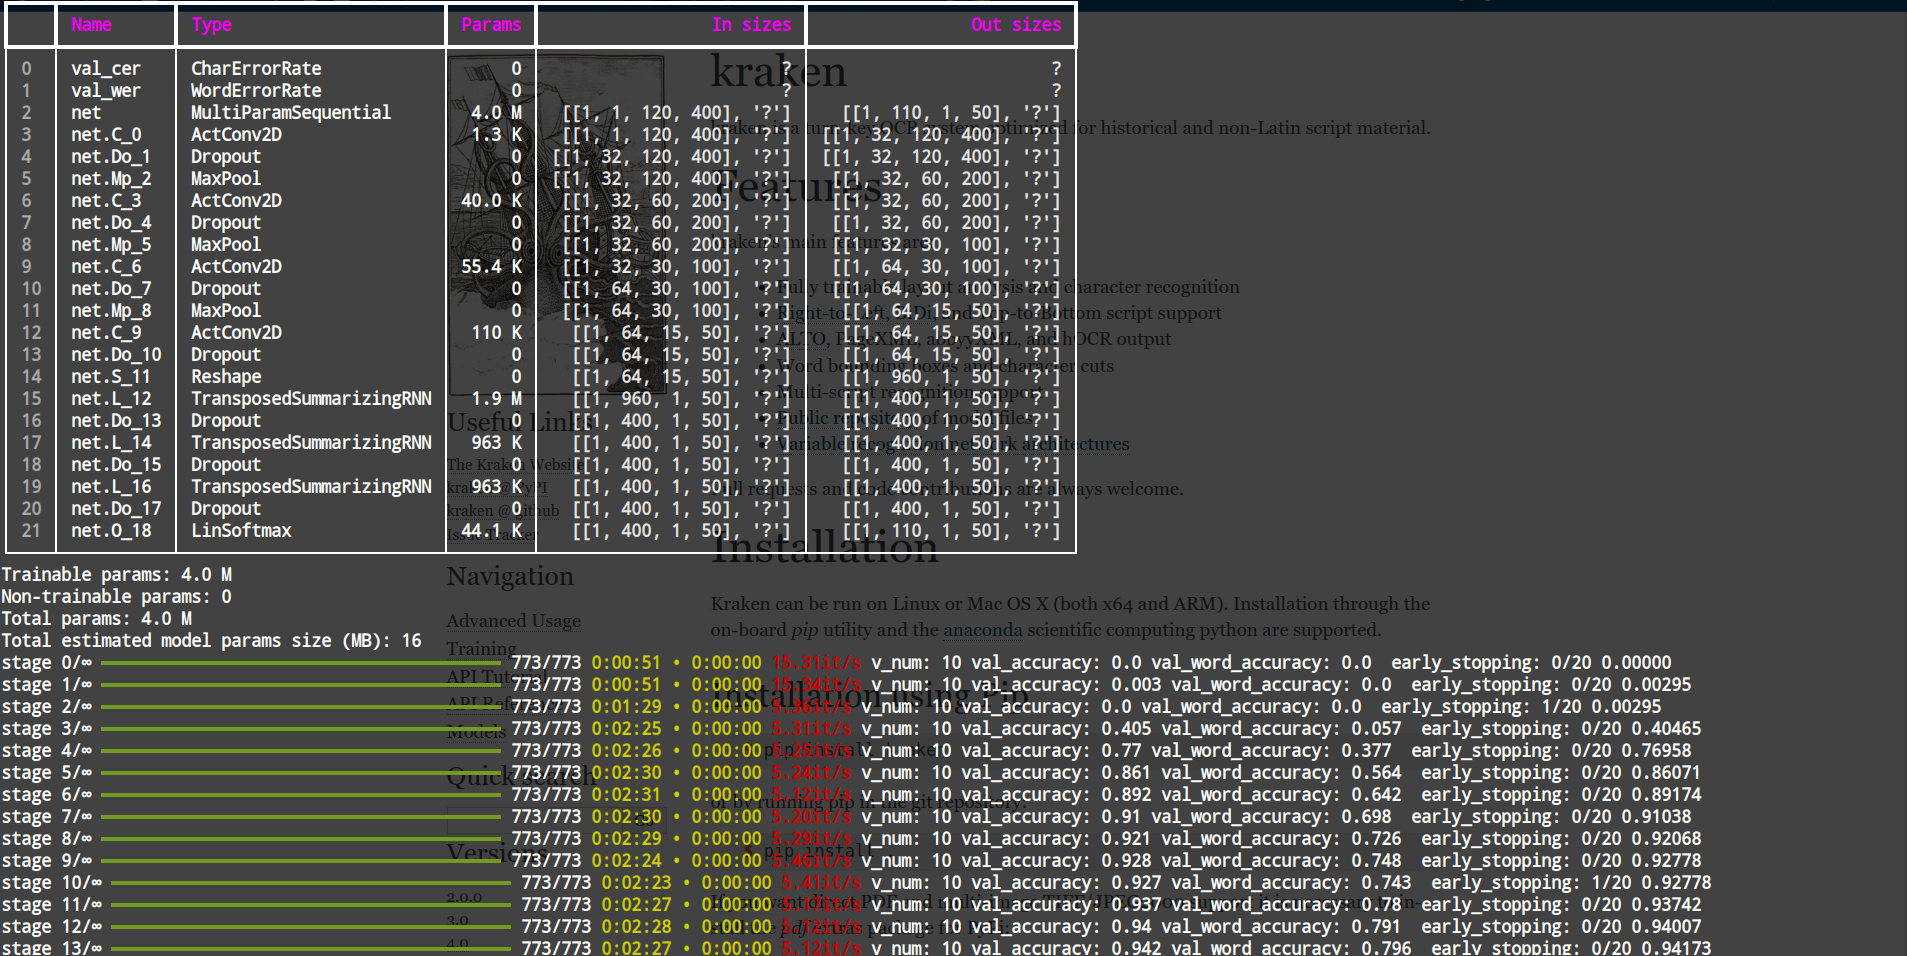
How to train custom OCR/HTR models in Kraken
“For every minute spent in organizing, an hour is earned,” Benjamin Franklin wrote. Personally, lack of organization has always been…
This post is prepared together with Tilman Schalmey (Trier University). Digital approaches changed a lot in the way we deal…
Guyin xiaojing 古音小鏡 is a database that gathers data and tools for Old Chinese linguistics, but not exclusively. I previously…
In my previous post on how to use the New Testament Virtual Manuscript Room (NTVMR), I walked through the process…
This is a guest post by Laurent Van Cutsem (Ghent University). Part II: The Database of Medieval Chinese Texts: A Critical…
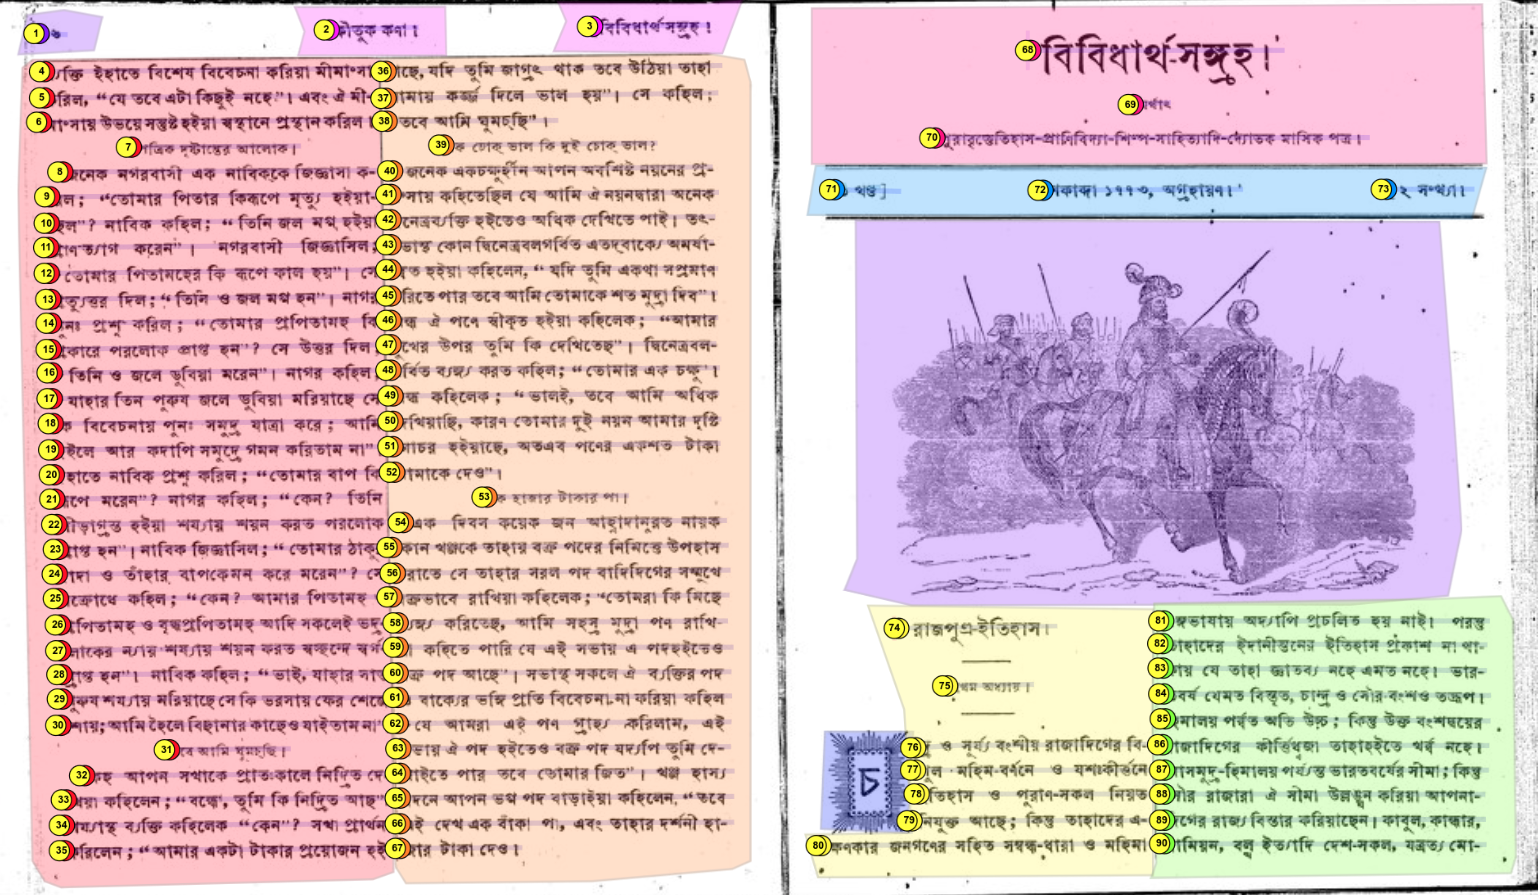
OCR of historical printing in Bengali using segmentation and recognition models trained in Kraken from an annotated dataset of Bengali texts published between 1860 and 1940.
This is a guest post by Sarah Blake LaRose. As a scholar of biblical studies who is blind, I often…