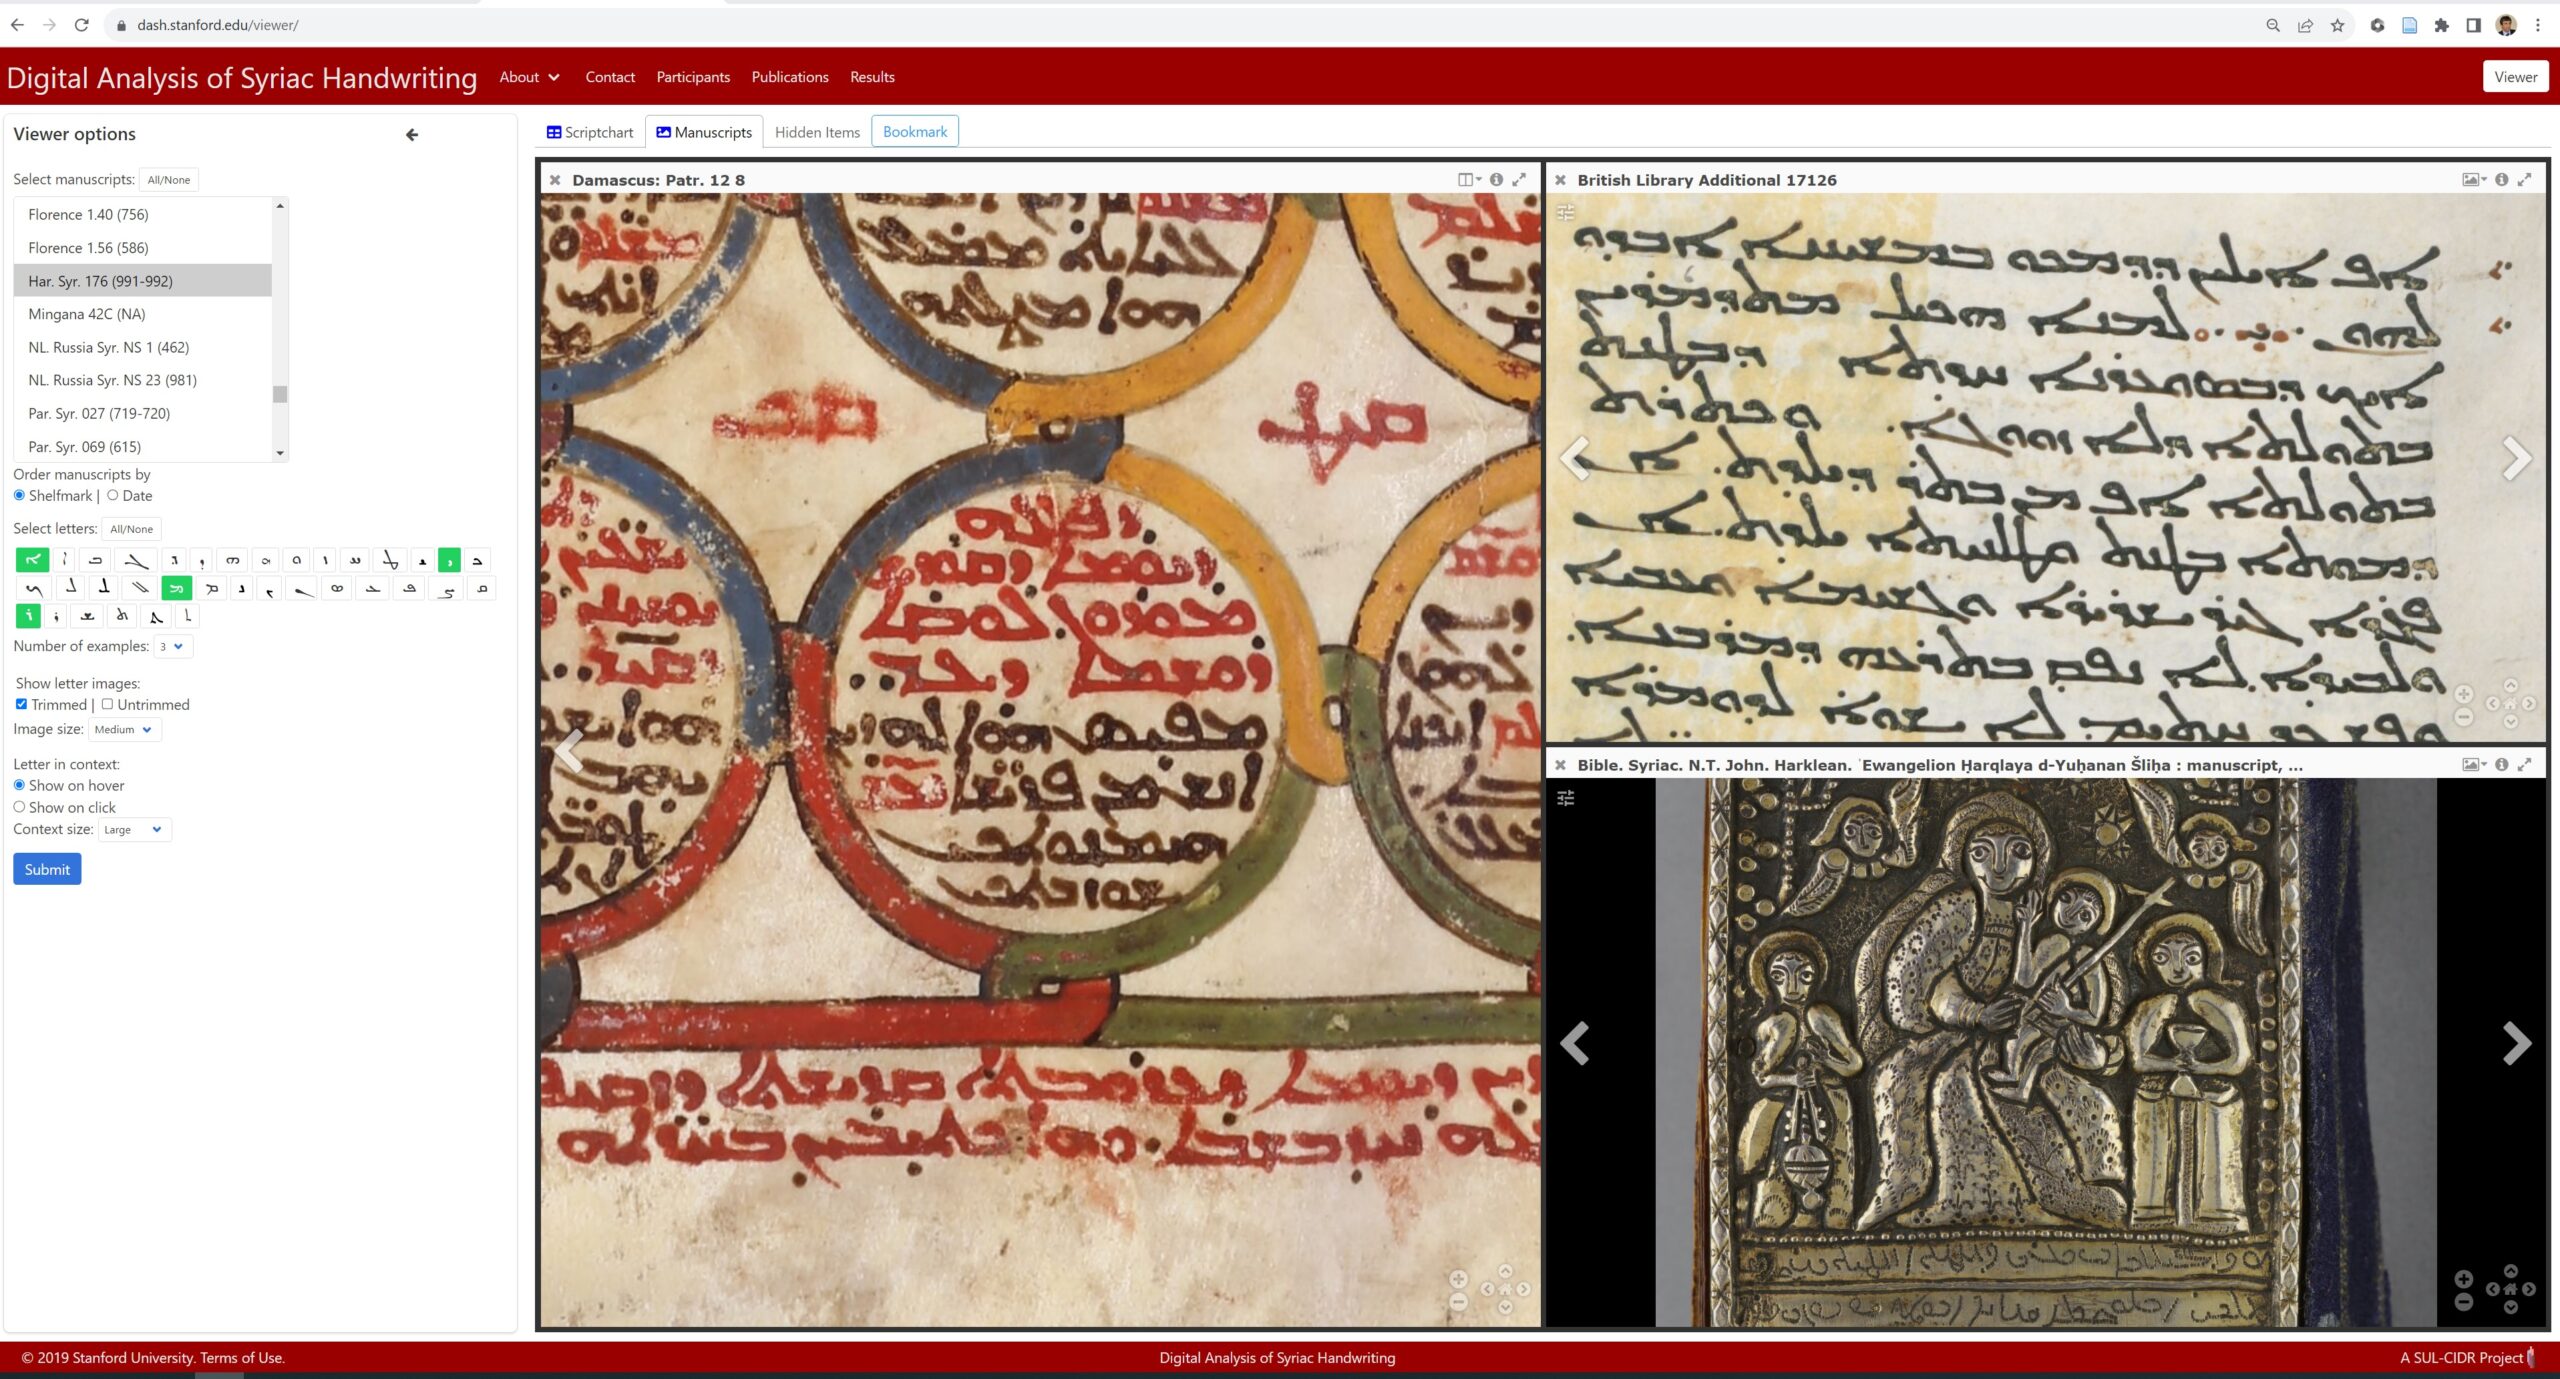
An Interview on DASH: Digital Analysis of Syriac Handwriting
In previous years I have posted some interviews with different projects to trace the history of the Syriac Digital Humanities.…
In previous years I have posted some interviews with different projects to trace the history of the Syriac Digital Humanities.…
Scholars working in the field of Korean studies have seen remarkable transformations in the way historical research is conducted. The…
While others have discussed the possibilities in utilizing Transkribus and other HTR resources in research, I want to briefly discuss…
Learn about Kraken’s segmentation model and the process of training our own custom segmentation models for layout analysis tasks.
The script used by the Christian cultures of Ethiopia is ancient, developing from the Sabaean script in the first centuries…
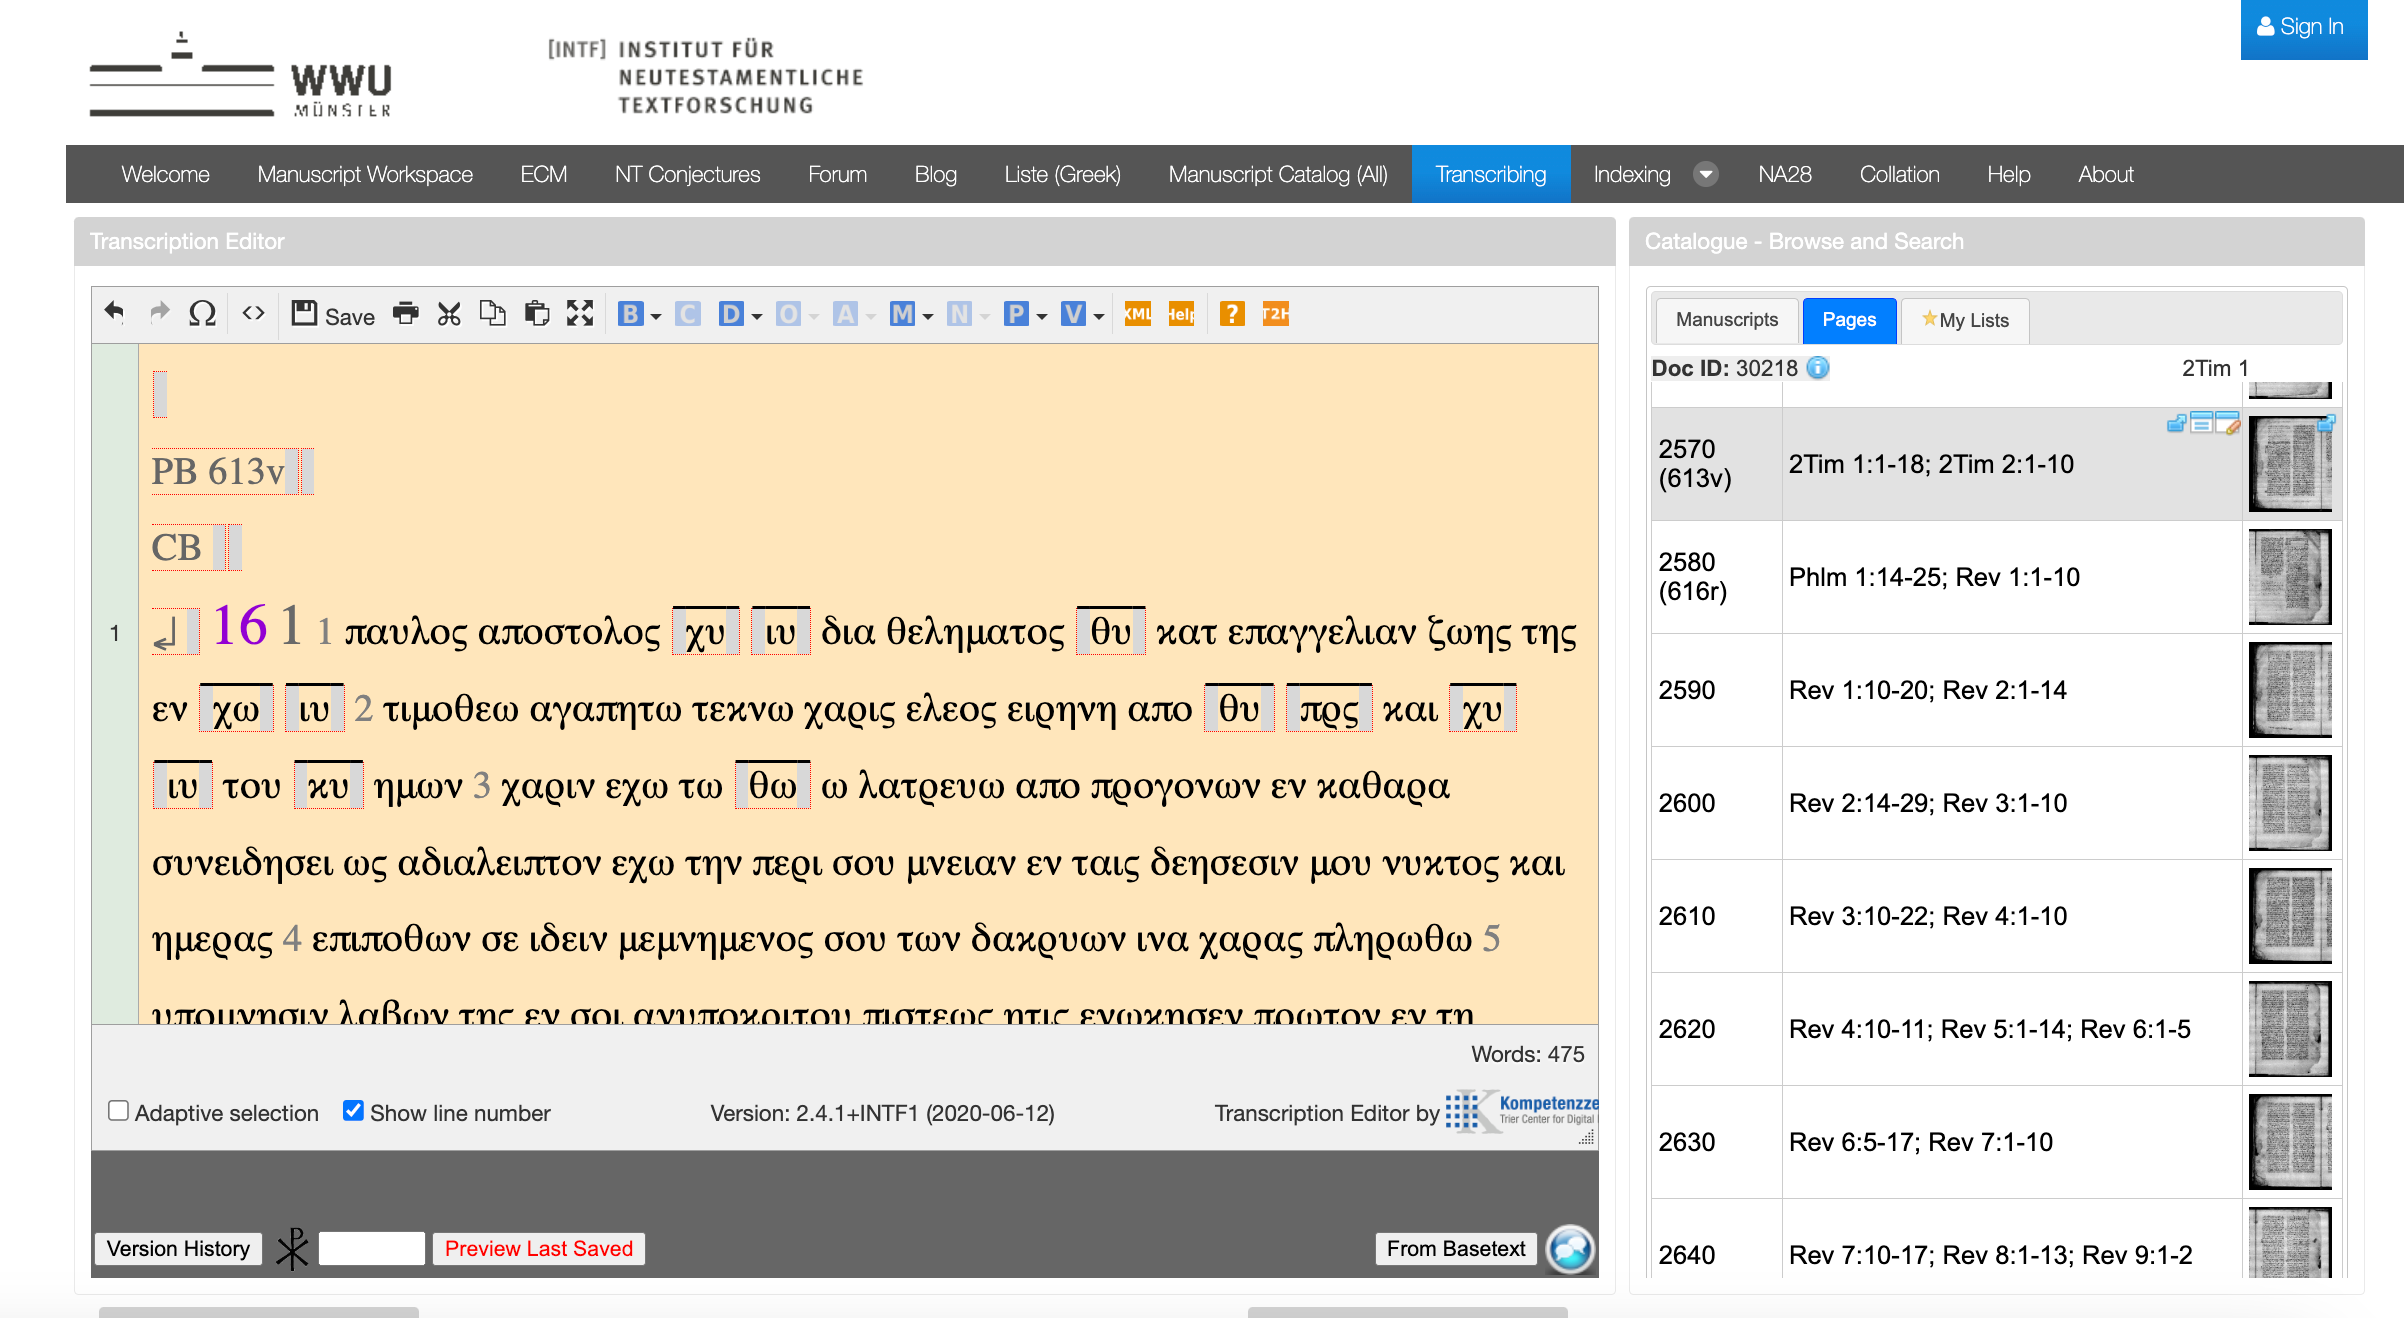
This post continues my series on using the New Testament Virtual Manuscript Room (NTVMR) for researching and transcribing Manuscripts of…
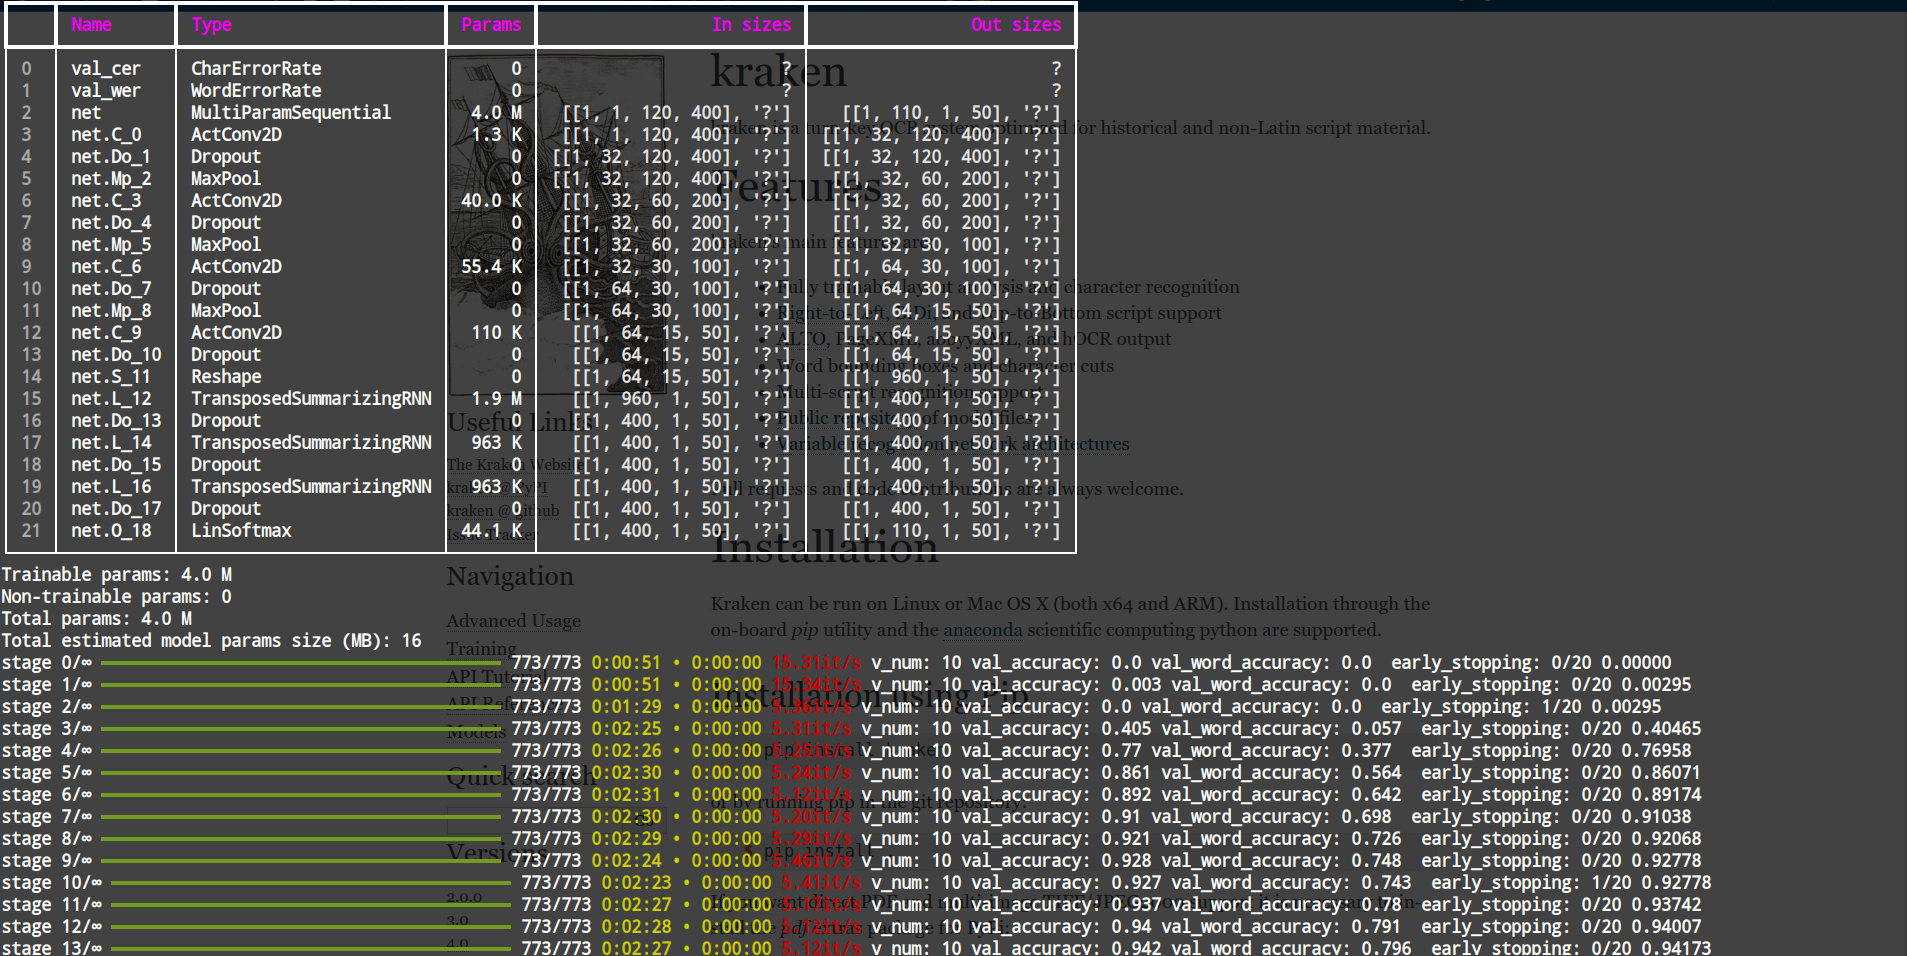
How to train custom OCR/HTR models in Kraken
Introduction: The READ Workbench and its Potential The READ (‘Research Environment for Ancient Documents’) Workbench, originally designed for interpreting and…
The technology of Natural Language Processing (NLP) identifies named entities, which are words or phrases referring to specific people, places,…
In my previous post on how to use the New Testament Virtual Manuscript Room (NTVMR), I walked through the process…