Current approaches on Automatic Recognition of Ethiopic script
The script used by the Christian cultures of Ethiopia is ancient, developing from the Sabaean script in the first centuries…
The script used by the Christian cultures of Ethiopia is ancient, developing from the Sabaean script in the first centuries…
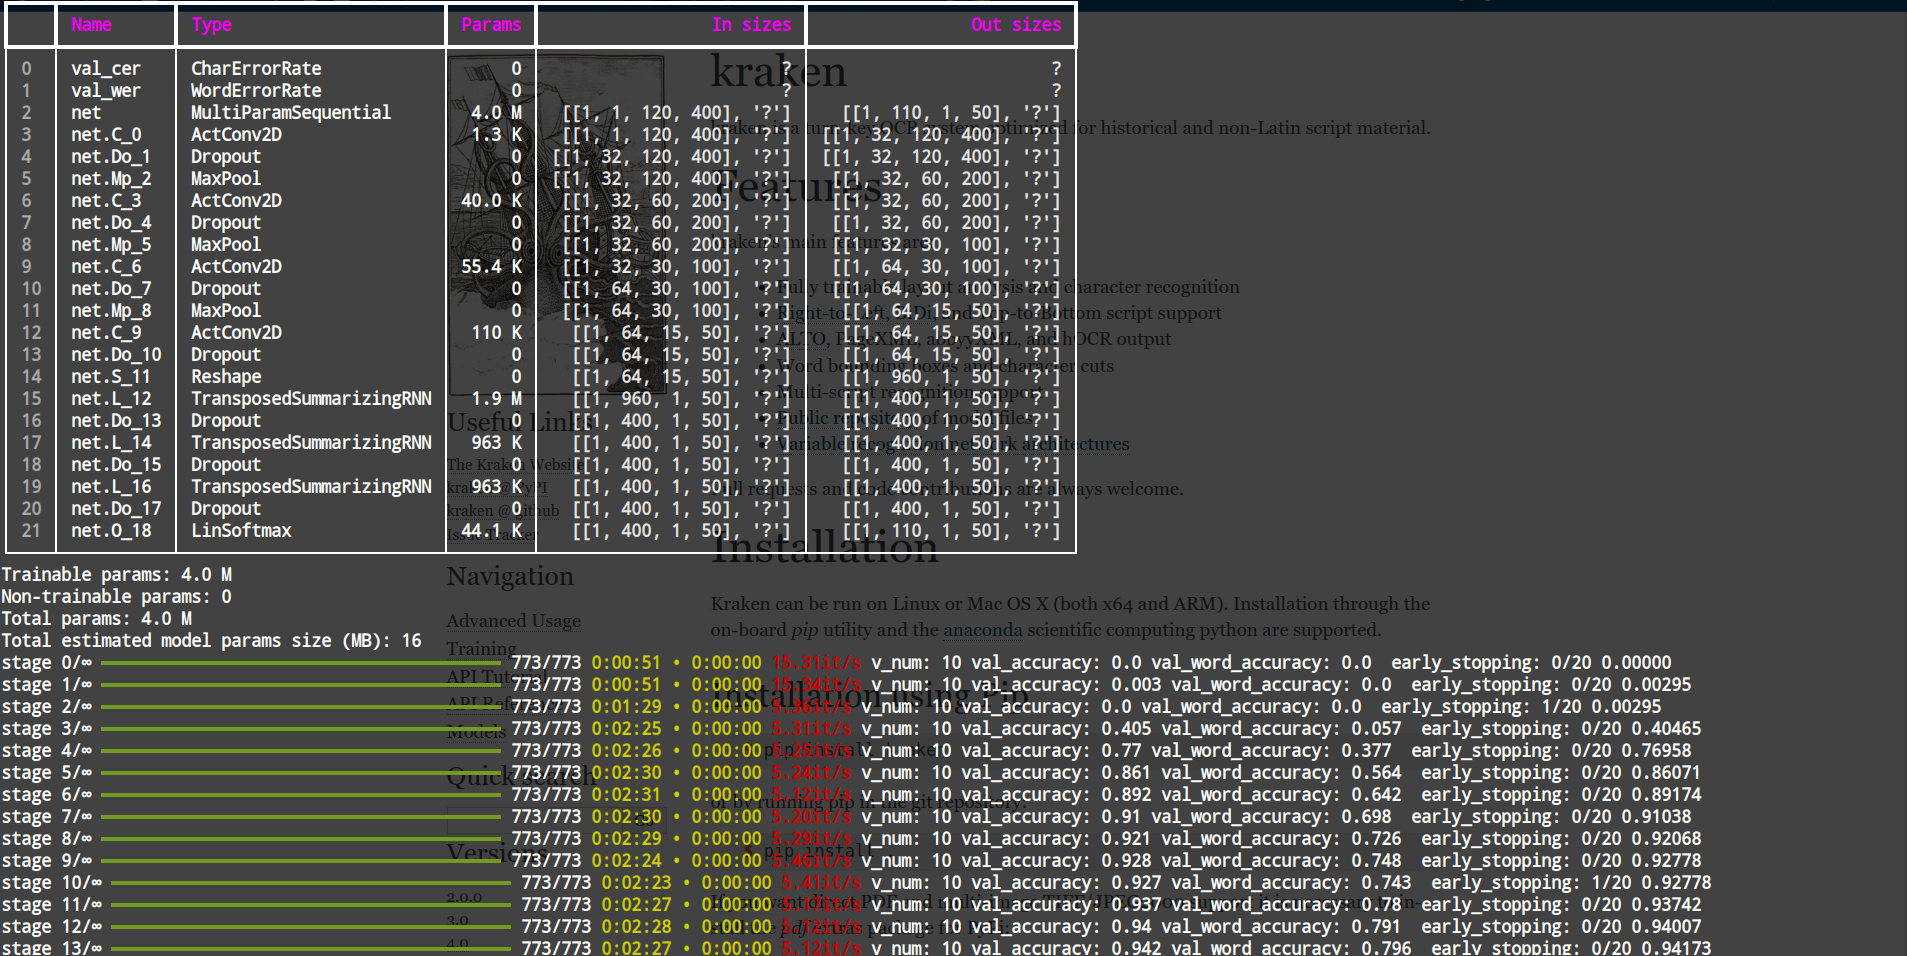
How to train custom OCR/HTR models in Kraken
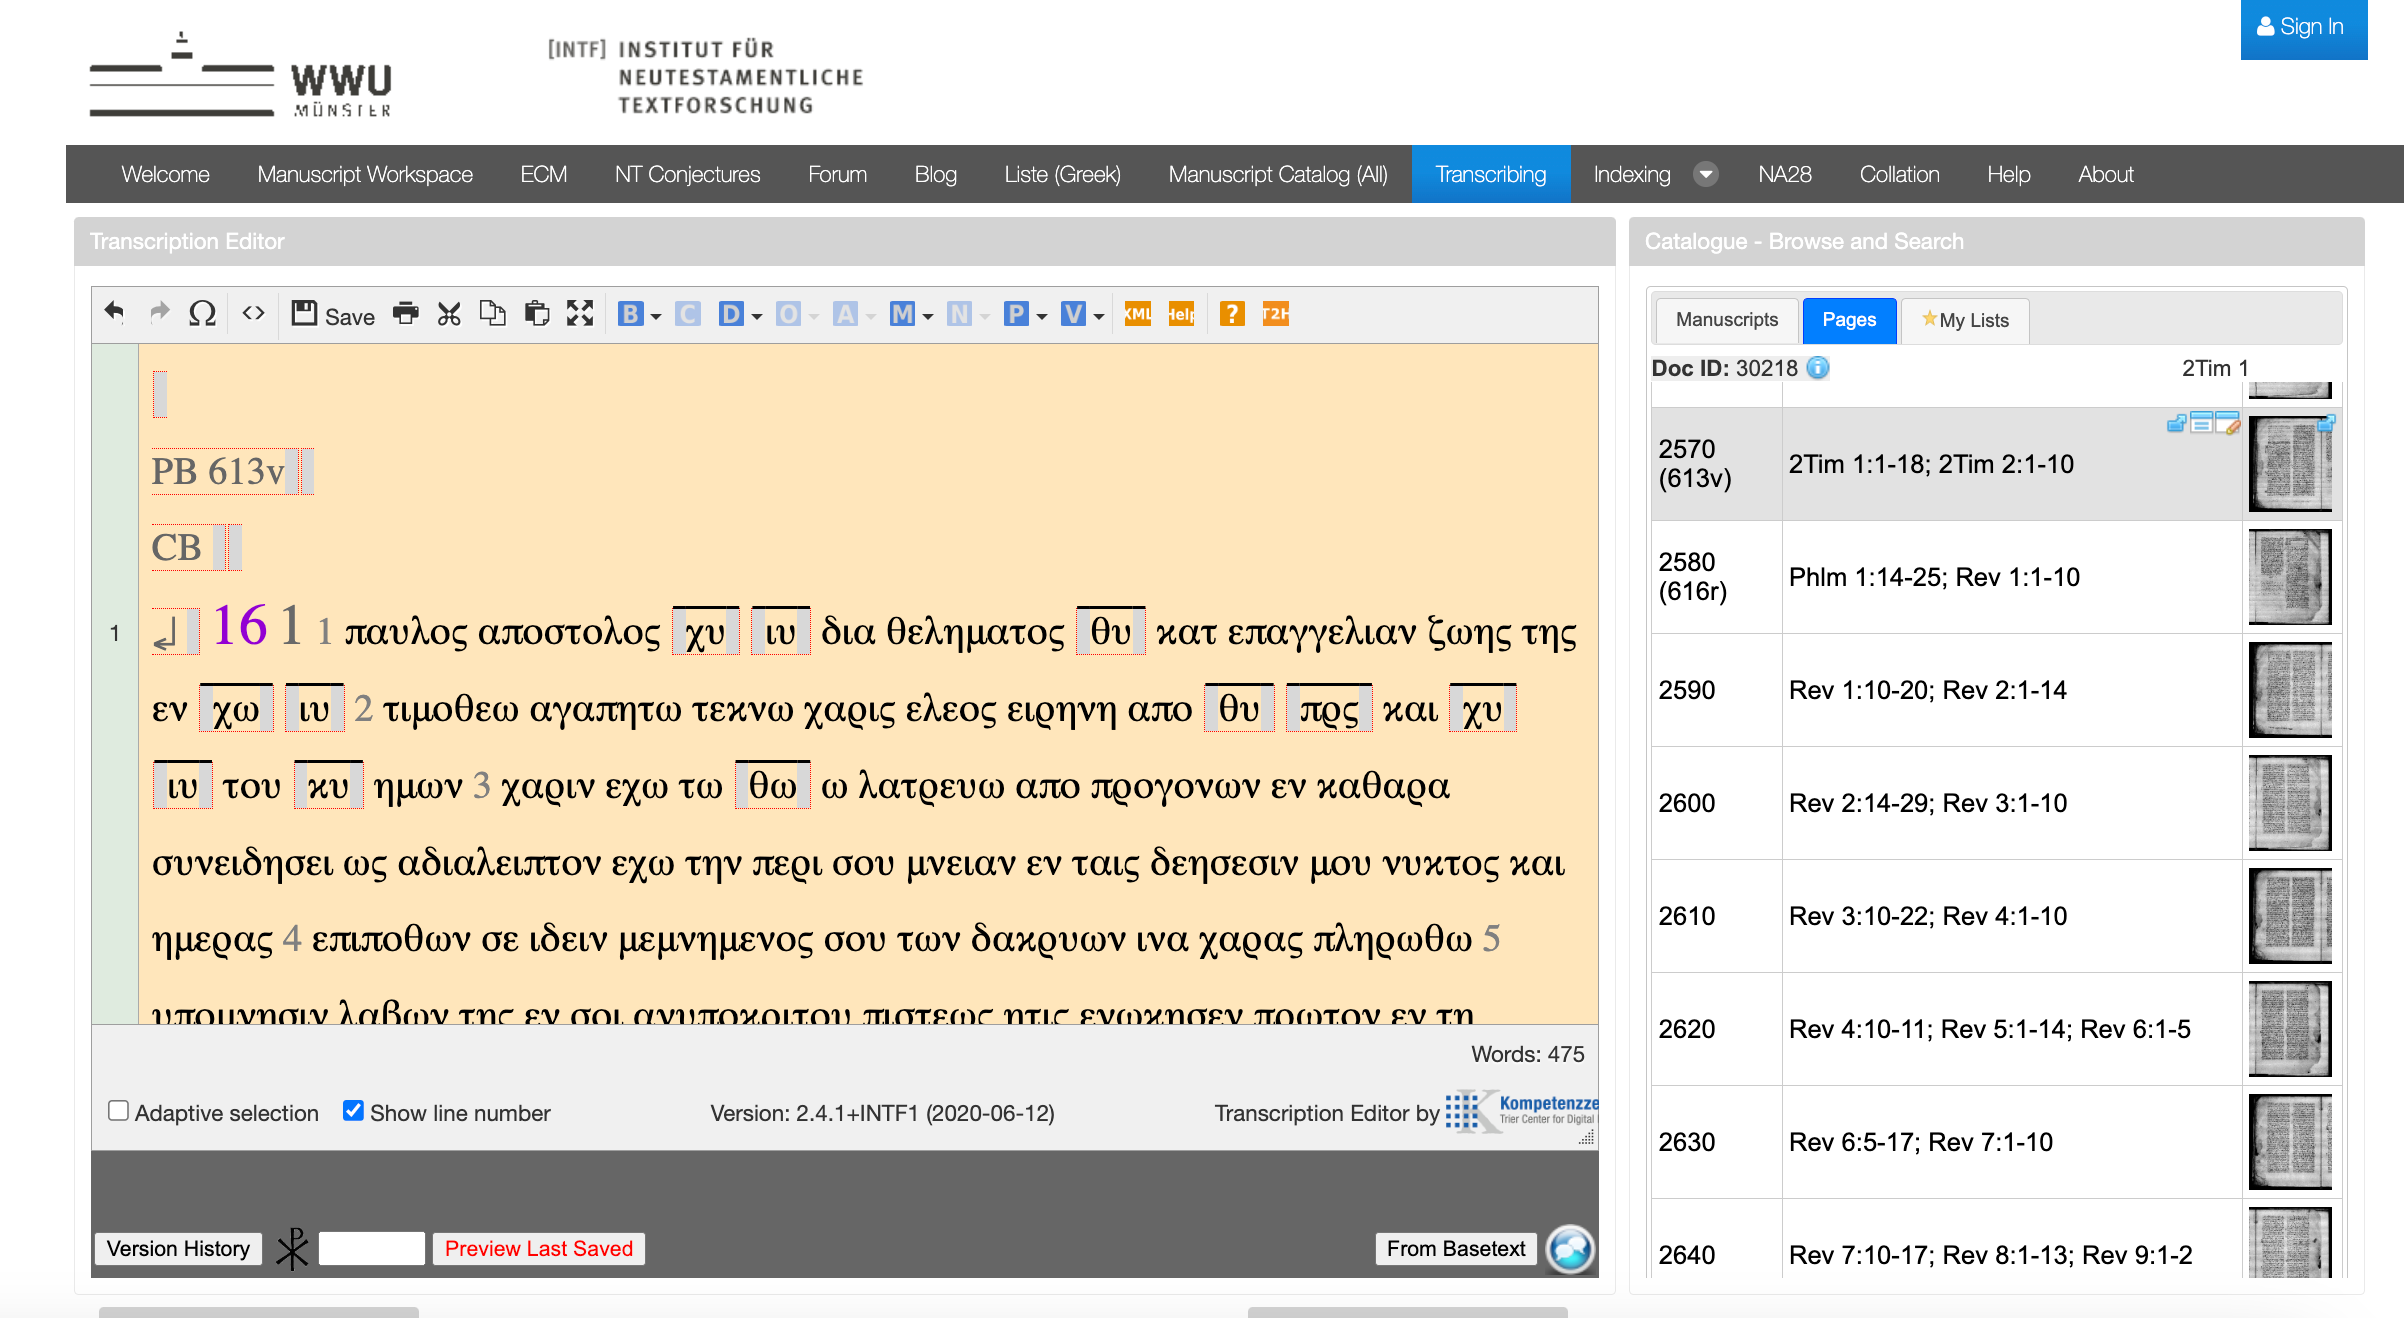
In my previous post on how to use the New Testament Virtual Manuscript Room (NTVMR), I walked through the process…
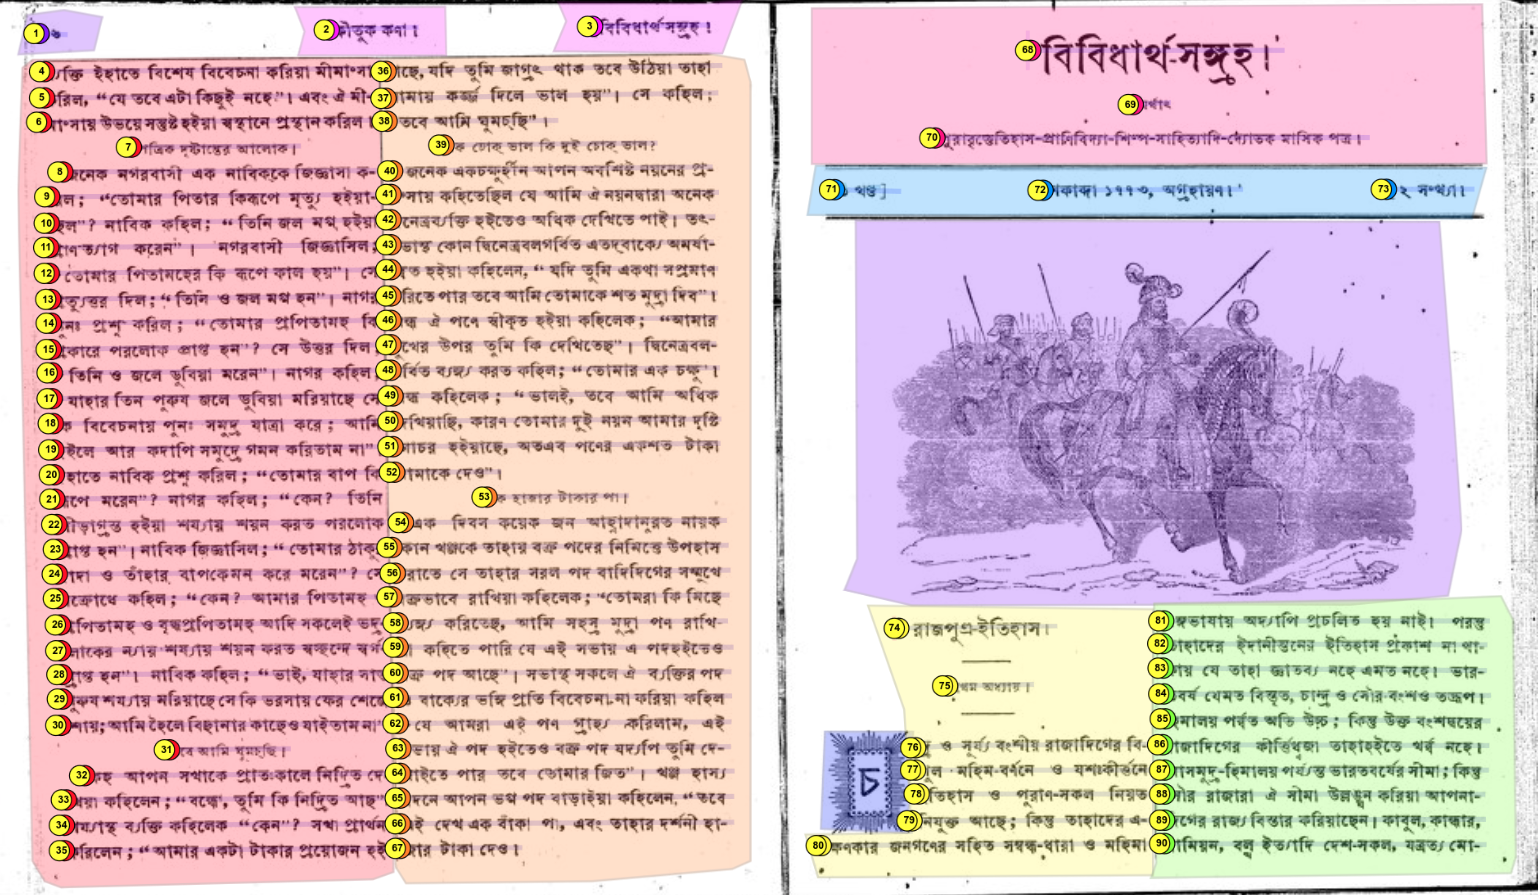
OCR of historical printing in Bengali using segmentation and recognition models trained in Kraken from an annotated dataset of Bengali texts published between 1860 and 1940.
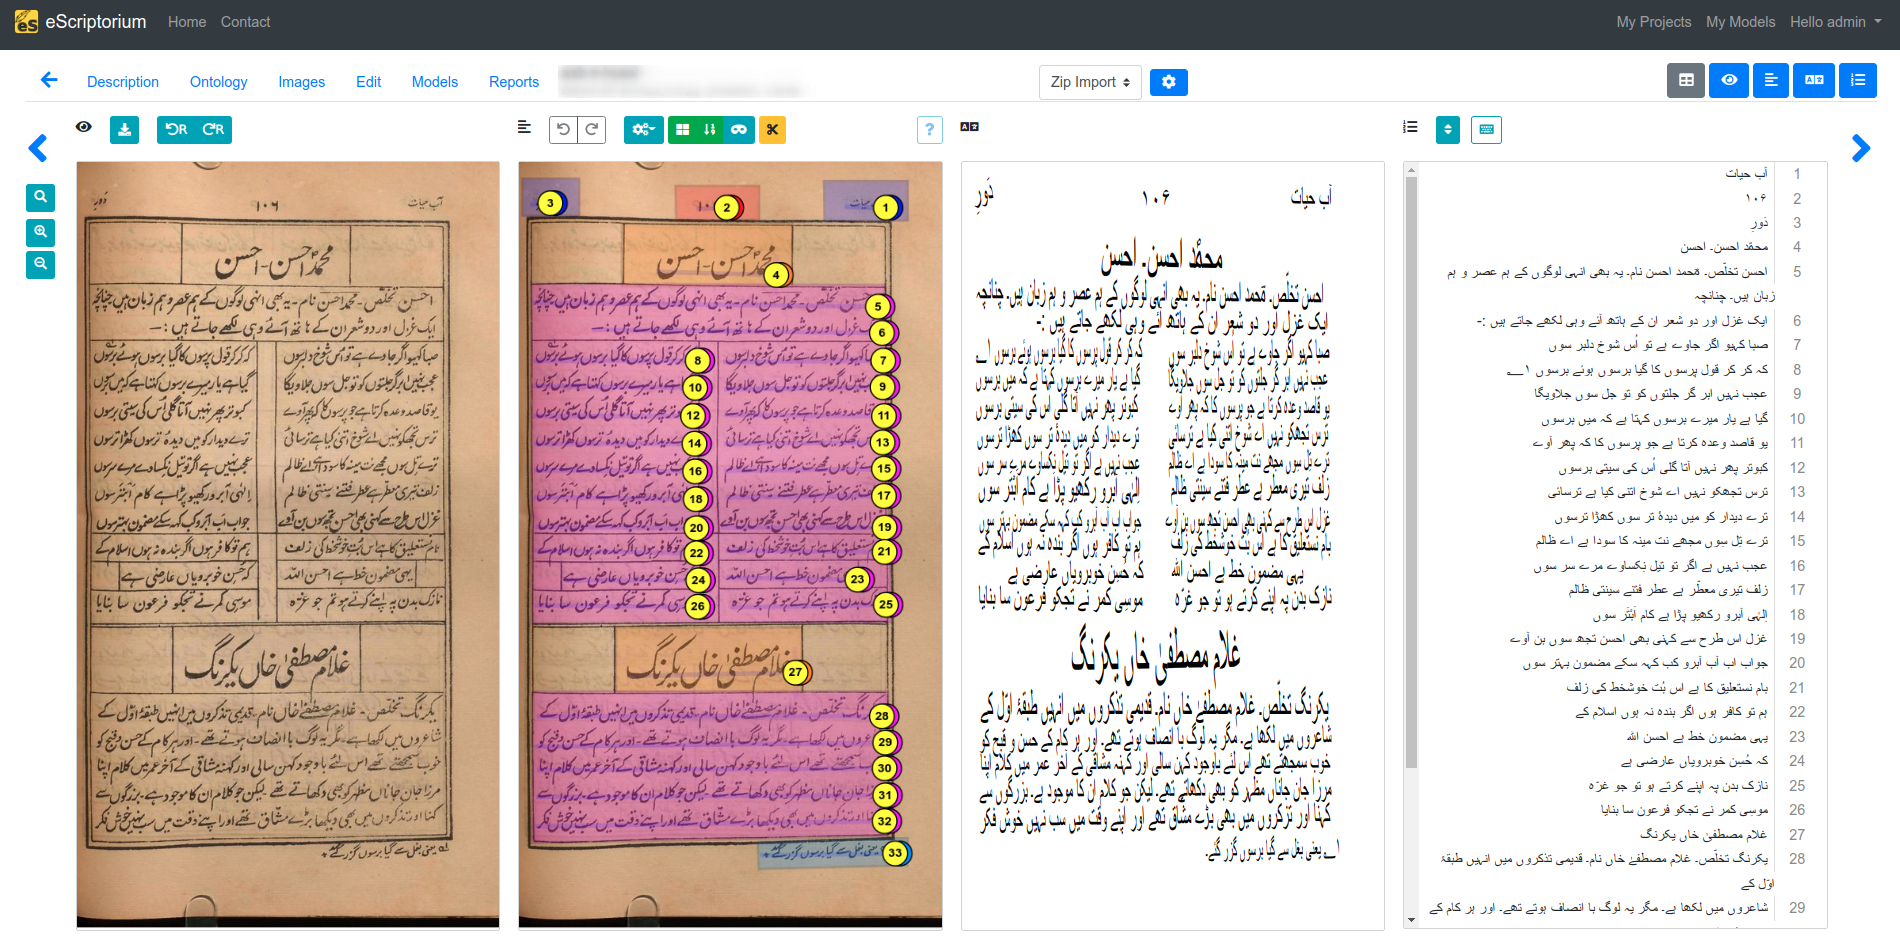
In part 1 of this series, I provided a quick introduction to eScriptorium and the workflow associated with it. This…
This is the third part of the interview with Arezou Azad, Senior Research Fellow at Oxford University’s Faculty of Asian…
(Part 2) Although we initially thought that the Ethiopian community would find something to satisfy its curiosity, it was clear…
State-of-the-art OCR engines use trainable models to perform two consecutive tasks that produce machine-actionable transcriptions. They first segment the position…
This is the second part of an interview with Arezou Azad, Senior Research Fellow at Oxford University’s Faculty of Asian…
In my last article, I wrote about my experiments to improve the accuracy of a Handwritten Text Recognition (HTR) model…